Chapterبەش 1 · Lectureوانە 1.2
AI Models Today: Claude, GPT, Gemini and Open Modelsمۆدێلەکانی ژیریی دەستکرد ئەمڕۆ: Claude، GPT، Gemini و مۆدێلە کێشکراوەکان
The AI models you can use today and how to think about them when the names change: company, model and product; the main families as of November 2026 (Claude, GPT, Gemini and open-weight models); big, middle and small tiers; reading a model page (ID, context window, max output, knowledge cutoff, price, retirement); reasoning models and effort; open versus closed weights; chat app, API or local; choosing a model with a small Python program; and testing claims with your own questions.
ئەو کە ئەمڕۆ دەتوانیت بەکاریان بهێنیت و چۆن بیریان لێ بکەیتەوە کاتێک ناوەکان دەگۆڕێن: کۆمپانیا، و بەرهەم؛ خێزانە سەرەکییەکان بەپێی تشرینی دووەمی 2026 (Claude، GPT، Gemini و )؛ ئاستی گەورە، ناوەند و بچووک؛ خوێندنەوەی پەڕەی (، ، زۆرترین ، ، نرخ، خانەنشینی)؛ و ئاستی هەوڵ؛ کراوە بەرامبەر داخراو؛ گفتوگۆ، API یان ناوخۆیی؛ هەڵبژاردنی بە بچووکی Python؛ هەروەها تاقیکردنەوەی بانگەشەکان بە پرسیارەکانی خۆت.
What you will learnچی فێر دەبیت
- Tell a company, a model and a product apart, and name examples as of November 2026.
- Explain model tiers and pick a suitable tier for a task.
- Read a model page: ID, context window, max output, knowledge cutoff, price and retirement.
- Explain what a reasoning model does and why it costs more.
- Compare open-weight and closed-weight models and the three ways to use a model.
- Choose a model with a small Python program and test claims with your own questions.
- کۆمپانیا، و بەرهەم لە یەکتر جیا بکەیتەوە و نموونەکانی تشرینی دووەمی 2026 بناسیت.
- ئاستەکانی ڕوون بکەیتەوە و ئاستێکی گونجاو بۆ ئەرکێک هەڵبژێریت.
- پەڕەی بخوێنیتەوە: ، ، زۆرترین ، ، نرخ و خانەنشینی.
- ڕوون بکەیتەوە چی دەکات و بۆچی گرانترە.
- و و سێ ڕێگاکەی بەکارهێنانی بەراورد بکەیت.
- بە بچووکی Python هەڵبژێریت و بانگەشەکان بە پرسیارەکانی خۆت تاقی بکەیتەوە.
Names change, ideas stayناوەکان دەگۆڕێن، بیرۆکەکان دەمێننەوە
Aram's friends talk about AI every day: ChatGPT, Claude, Gemini, DeepSeek, an open model in the college lab. New names appear every few months, and last year's best model is soon replaced. If you learn only the names, your knowledge is old by next term.
هاوڕێکانی ئارام هەموو ڕۆژێک باسی دەکەن: ChatGPT، Claude، Gemini، DeepSeek، کراوە لە تاقیگەی کۆلێژ. هەر چەند مانگێک ناوی نوێ دەردەکەون و باشترین ساڵی ڕابردوو زوو جێگەی دەگیرێتەوە. ئەگەر تەنیا ناوەکان فێر بیت، زانیارییەکەت تا وەرزی داهاتوو کۆن دەبێت.
This lesson teaches the ideas that stay: who makes a model and how you reach it, model sizes, the numbers on a model page, thinking models, open and closed weights, and how to choose and test a model. Names appear only as examples, as of November 2026.
ئەم وانەیە ئەو بیرۆکانە فێر دەکات کە دەمێننەوە: کێ دروست دەکات و چۆن دەیگەیتێ، قەبارەی ، ژمارەکانی سەر پەڕەی ، ، کراوە و داخراو، هەروەها چۆن هەڵبژێریت و تاقی بکەیتەوە. ناوەکان تەنیا وەک نموونە دێن، بەپێی تشرینی دووەمی 2026.
Company, model, productکۆمپانیا، مۆدێل، بەرهەم
Three layers are easy to mix up. A company (Anthropic, OpenAI, Google) trains a model (Claude Opus 5.5, GPT-6.1 Sol, Gemini 3.8 Flash). People reach the model through a product: a chat app (the Claude app, ChatGPT, the Gemini app) or the company's API for programmers. So ChatGPT is not a model: it is an app that uses OpenAI's models.
سێ چین بە ئاسانی تێکەڵ دەکرێن. کۆمپانیایەک (Anthropic، OpenAI، Google) ڕادەهێنێت (Claude Opus 5.5، GPT-6.1 Sol، Gemini 3.8 Flash). خەڵک لە ڕێگەی بەرهەمێکەوە دەگەنە : گفتوگۆ ( Claude، ChatGPT، Gemini) یان کۆمپانیاکە بۆ . کەواتە ChatGPT نییە: کە OpenAI بەکار دەهێنێت.
A car company designs engines and puts them into cars. You drive the car, not the engine. The same engine can sit in several cars, and next year's car may get a new engine. The model is the engine; the app is the car.
کۆمپانیایەکی ئۆتۆمبێل بزوێنەر دیزاین دەکات و دەیخاتە ناو ئۆتۆمبێلەکانەوە. تۆ ئۆتۆمبێلەکە لێدەخوڕیت، نەک بزوێنەرەکە. هەمان بزوێنەر دەکرێت لە چەند ئۆتۆمبێلێکدا بێت و ئۆتۆمبێلی ساڵی داهاتوو دەشێت بزوێنەرێکی نوێی هەبێت. بزوێنەرەکەیە؛ ئۆتۆمبێلەکەیە.
Where the analogy stops workingسنووری ئەم نموونەیە
A car has one engine; an AI app often lets you switch between several models, and the company can change them quietly.
ئۆتۆمبێل یەک بزوێنەری هەیە؛ زۆرجار ڕێگەت دەدات لە نێوان چەند بگۆڕیت و کۆمپانیاکە دەتوانێت بێدەنگ بیانگۆڕێت.
The main families in November 2026خێزانە سەرەکییەکان لە تشرینی دووەمی 2026دا
Each company offers a family of models in several sizes. The table lists the main ones from the providers' own pages, checked on 10 November 2026, biggest first.
هەر کۆمپانیایەک خێزانێک بە چەند قەبارەیەک پێشکەش دەکات. خشتەکە سەرەکییەکان لە پەڕەکانی خودی دابینکەرانەوە دەنووسێت، کە لە 10ی تشرینی دووەمی 2026 پشکنراون، گەورەترین لە سەرەوە.
| Providerدابینکەر | Models, biggest first، گەورەترین یەکەم | Context window | Price per million tokens (input / output)نرخ بۆ هەر ملیۆن ( / ) |
|---|---|---|---|
| Anthropic (Claude) | Fable 5.2 · Opus 5.5 · Sonnet 5.5 · Haiku 5.5 | 1M tokens1 ملیۆن | $8 / $40 down to $0.10 / $0.50لە $8 / $40 تا $0.10 / $0.50 |
| OpenAI (GPT) | GPT-6 Astra · GPT-6.1 Sol · GPT-6.1 Terra · GPT-6 Luna | 1.05M tokens1.05 ملیۆن | $10 / $50 down to $0.10 / $0.50لە $10 / $50 تا $0.10 / $0.50 |
| Google (Gemini) | Gemini 4 Argon · Gemini 3.8 Flash · Gemini 3.5 Flash-Lite | 1,048,576 tokens (Argon, 3.8 Flash)1,048,576 (Argon، 3.8 Flash) | $2 / $10 (Argon; $4 / $20 from 1 December 2026) down to $0.30 / $2.50لە $2 / $10 (Argon؛ لە 1ی کانوونی یەکەمی 2026ـەوە $4 / $20) تا $0.30 / $2.50 |
| Open-weight makersدروستکەرانی | Mistral Large 4, Mistral Small 4, Ministral 3 · DeepSeek V4.1 Flash · Z.ai GLM 5.3 · Meta Muse Spark Open · OpenAI gpt-oss-120b, gpt-oss-20bMistral Large 4، Mistral Small 4، Ministral 3 · DeepSeek V4.1 Flash · Z.ai GLM 5.3 · Meta Muse Spark Open · OpenAI gpt-oss-120b، gpt-oss-20b | depends on the modelبەپێی | free to download; you pay for the hardware or a host بێبەرانبەرە؛ پارەی ئامێر یان دەدەیت |
Big, middle and small modelsمۆدێلی گەورە، ناوەند و بچووک
Inside a family, bigger models (more weights) are usually better at hard reasoning but slower and more expensive. Smaller ones are fast and cheap and good enough for simple jobs. Anthropic, for example, describes Claude Haiku 5.5 as made for high-volume tasks such as classification, and Claude Fable 5.2 for demanding reasoning. Think of an expert consultant, an experienced worker and a fast apprentice: you do not pay the consultant to sort the post.
لە ناو خێزانێکدا، گەورەکان ( زیاتر) زۆرجار لە بیرکردنەوەی قورسدا باشترن، بەڵام هێواشتر و گرانترن. بچووکەکان خێرا و هەرزانن و بۆ کاری سادە بەسن. بۆ نموونە Anthropic دەڵێت Claude Haiku 5.5 بۆ ئەرکی زۆر و دووپاتە وەک دروست کراوە و Claude Fable 5.2 بۆ بیرکردنەوەی قورس. بیر لە ڕاوێژکارێکی شارەزا، کرێکارێکی بە ئەزموون و شاگردێکی خێرا بکەرەوە: پارە بە ڕاوێژکار نادەیت بۆ ئەوەی نامەکانی پۆستە ڕیز بکات.
A with far fewer than the biggest ones. It is cheaper and faster, can sometimes run on a laptop or phone, and is good enough for simple tasks such as sorting messages.
کە زۆر کەمتری هەیە لە گەورەترینەکان. هەرزانتر و خێراترە، هەندێک جار لەسەر لاپتۆپ یان مۆبایل کار دەکات و بۆ ئەرکی سادە وەک ڕیزکردنی نامەکان بەسە.
Reading a model pageخوێندنەوەی پەڕەی مۆدێلێک
Every provider publishes the same few numbers for each model. Learn to read them once and you can compare any model:
هەموو دابینکەرێک هەمان چەند ژمارە بۆ هەر بڵاو دەکاتەوە. یەک جار فێری خوێندنەوەیان ببە و دەتوانیت هەر بەراورد بکەیت:
- Model ID: the exact name your program sends, such as
claude-opus-5-5. - Context window: how many tokens the model can look at in one request, your text and its answer together. On Claude's current tokenizer, 1M tokens is roughly 555,000 English words (tokens and the context window).
- Max output: the longest answer in one go (128K tokens here).
- Knowledge cutoff: the date its training data ends (next screen).
- Price: dollars per million input tokens and per million output tokens; here output costs five times more (how pricing works).
- Retirement: the earliest date the model may be switched off, so apps must move to a newer one before it.
- : ئەو ناوە وردەی دەینێرێت، وەک
claude-opus-5-5. - : چەند دەتوانێت لە یەک سەیری بکات، دەقەکەی تۆ و وەڵامەکەی پێکەوە. لەسەر تۆکنکەرە ئێستاییەکەی Claude، 1 ملیۆن نزیکەی 555,000 وشەی ئینگلیزییە (تۆکنەکان و پەنجەرەی کۆنتێکست).
- زۆرترین : درێژترین وەڵام بە یەکجار (لێرەدا 128 هەزار ).
- : ئەو ڕێکەوتەی تێیدا کۆتایی دێت (شاشەی داهاتوو).
- نرخ: دۆلار بۆ هەر ملیۆن و هەر ملیۆن ؛ لێرەدا پێنج هێندە گرانترە (نرخ چۆن کار دەکات).
- خانەنشینی: زووترین ڕێکەوت کە دەشێت بکوژێنرێتەوە، بۆیە دەبێت پێش ئەو ڕێکەوتە بگوازنەوە بۆ نوێتر.
The knowledge cutoffڕێکەوتی بڕانی زانیاری
A model learns only from text written before its training data ends. That date is its knowledge cutoff: June 2026 for the current Claude models, and between 30 April and 1 June 2026 for OpenAI's GPT-6 family (as of November 2026). Ask about a football match from October 2026 and the model can only guess, or should say it does not know. It does not even know today's date unless the app tells it.
تەنیا لەو دەقانە فێر دەبێت کە پێش کۆتایی نووسراون. ئەو ڕێکەوتە پێی دەوترێت : بۆ ئێستاییەکانی Claude حوزەیرانی 2026 و بۆ خێزانی GPT-6ی OpenAI لە نێوان 30ی نیسان و 1ی حوزەیرانی 2026دا (بەپێی تشرینی دووەمی 2026). لەبارەی یارییەکی تۆپی پێی تشرینی یەکەمی 2026 بپرسە و تەنیا دەتوانێت مەزەندە بکات، یان دەبێت بڵێت نایزانێت. تەنانەت ڕێکەوتی ئەمڕۆش نازانێت، مەگەر پێی بڵێت.
Apps fix this by giving the model fresh text, for example from a web-search tool: a tool the app runs for the model (tool use). Anthropic also lists a reliable knowledge cutoff: the model knows the most, and the most reliably, about the time before it.
ئەمە بەوە چارەسەر دەکەن کە دەقی نوێ دەدەنە ، بۆ نموونە لە ئامرازێکی گەڕانی وێبەوە: ئامرازێک کە بۆ کاری پێدەکات (بەکارهێنانی ئامراز). Anthropic هەروەها متمانەپێکراو دەنووسێت: زۆرترین و متمانەپێکراوترین زانیاری لەبارەی کاتی پێش ئەو ڕێکەوتە هەیە.
The date after which a has seen no . It does not know about later events unless an app gives it fresh information, for example from a web search.
ئەو ڕێکەوتەی کە دوای ئەو هیچ دەقێکی نوێ لە نییە. مۆدێلەکە ئاگای لە ڕووداوەکانی دواتر نییە، مەگەر ئەپەکە زانیاریی نوێی پێبدات، بۆ نموونە لە گەڕانێکی وێبەوە.
Reasoning models: thinking before answeringمۆدێلە بیرکەرەوەکان: بیرکردنەوە پێش وەڵامدانەوە
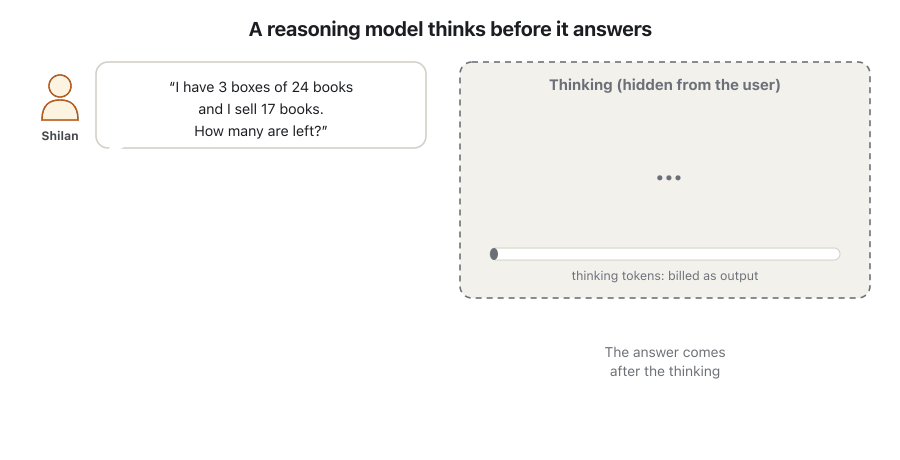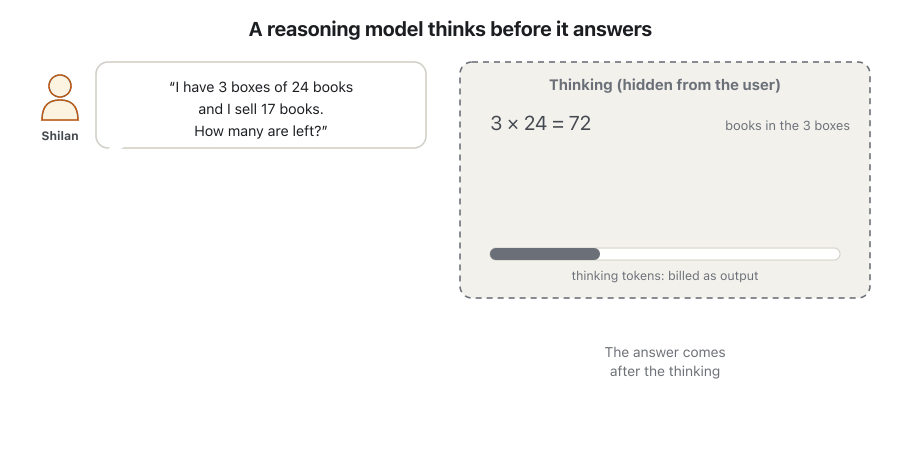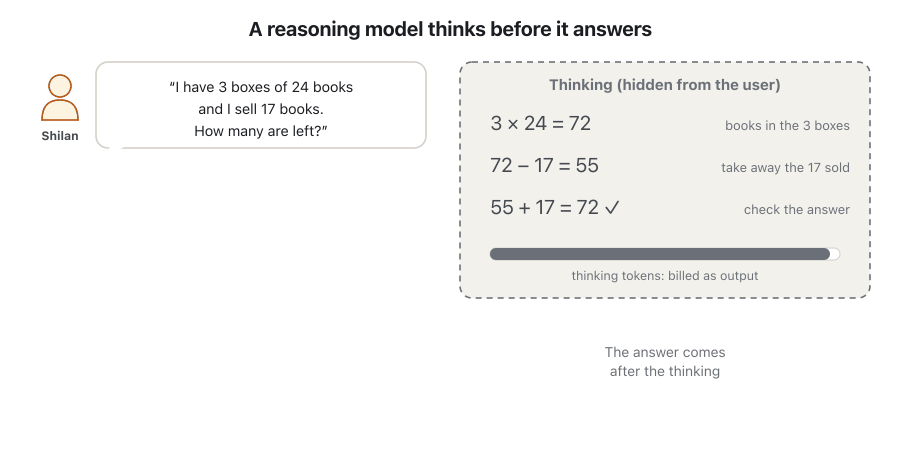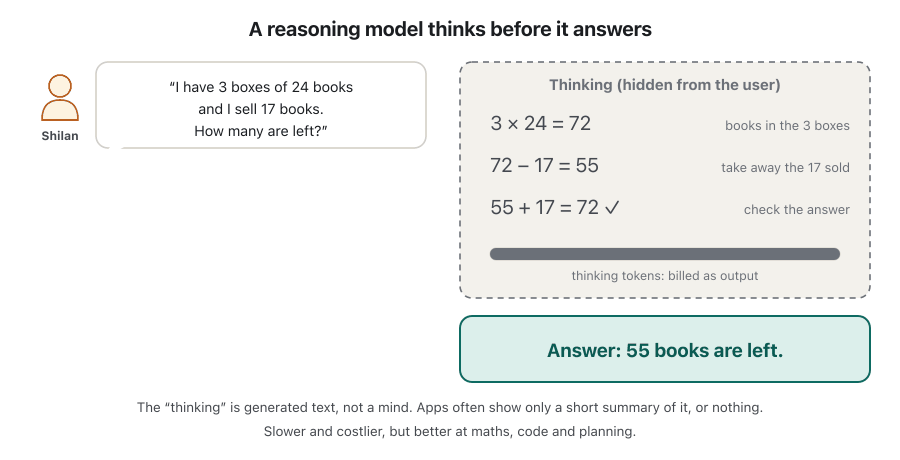
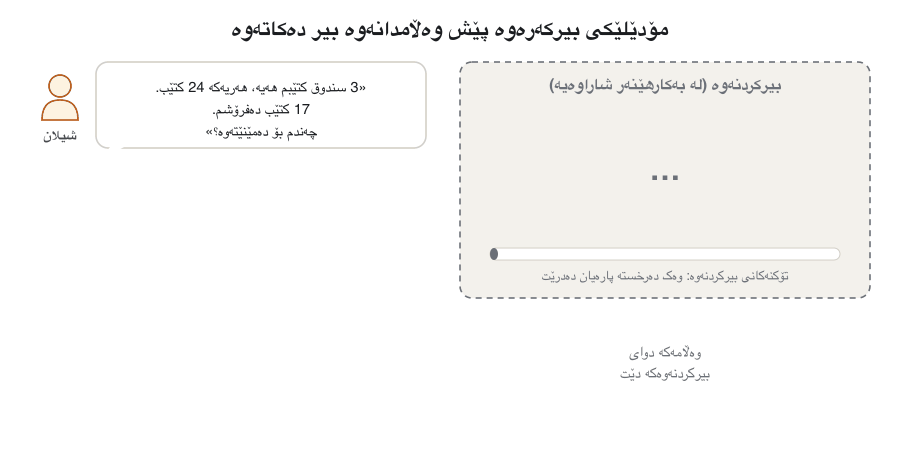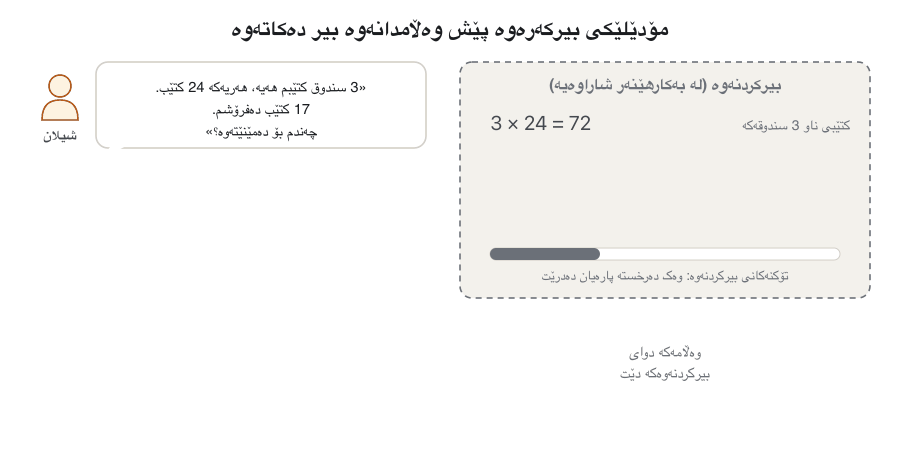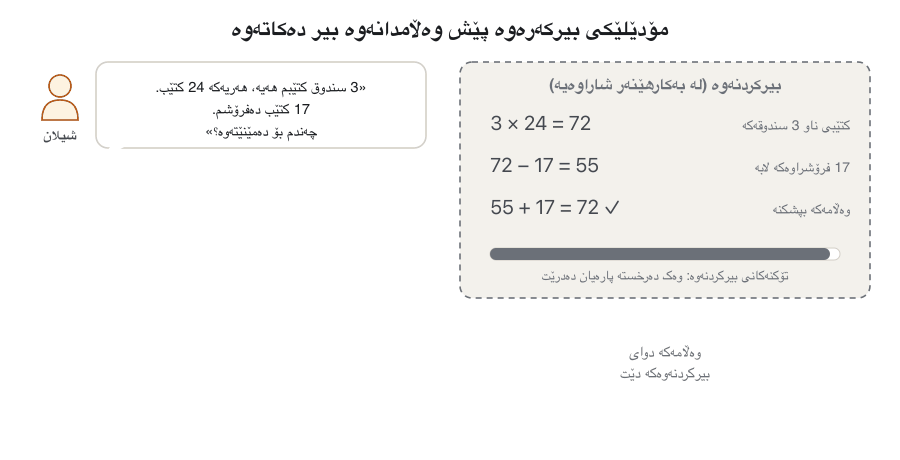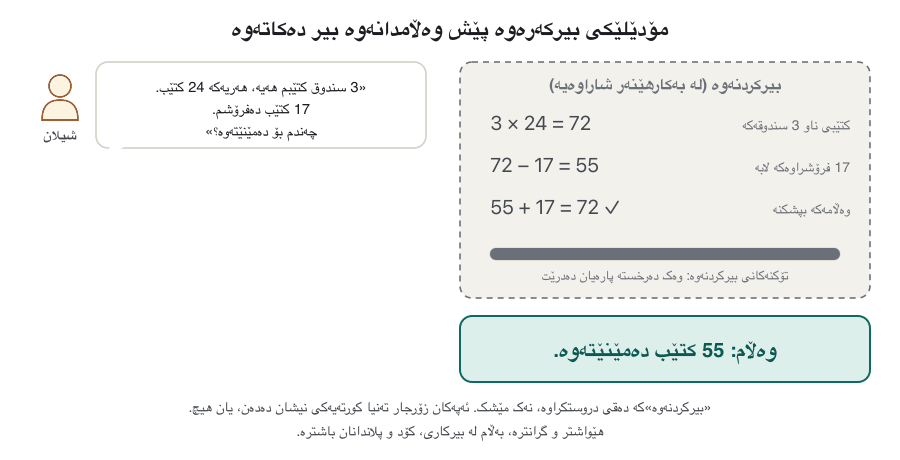
A reasoning model writes out steps, its “thinking”, before the final answer. OpenAI's o1-preview (September 2024) was the first widely used one. As of November 2026 every current Claude model thinks by default and decides how much to think, and the GPT-6 and Gemini models let you choose a reasoning level. Thinking helps with maths, code and planning, but it is slower and costs more: thinking tokens are billed as output tokens, even when you do not see them.
پێش وەڵامی کۆتایی هەنگاوەکان دەنووسێت، واتە «بیرکردنەوە»کەی. o1-previewـی OpenAI (ئەیلوولی 2024) یەکەمیان بوو کە زۆر بەکار هات. بەپێی تشرینی دووەمی 2026، هەموو ئێستای Claude بە شێوەی بنەڕەتی بیر دەکاتەوە و خۆی بڕیار دەدات چەندە بیر بکاتەوە، هەروەها GPT-6 و Gemini ڕێگەت دەدەن ئاستی بیرکردنەوە هەڵبژێریت. بیرکردنەوە لە بیرکاری، کۆد و پلاندانان یارمەتی دەدات، بەڵام هێواشترە و گرانترە: بیرکردنەوە وەک پارەیان لێ وەردەگیرێت، تەنانەت کاتێک نایانبینیت.
You steer it with an effort level. Claude's levels are low, medium, high, xhigh and max: low is quick and cheap, higher levels think longer on hard problems. Remember that the thinking is generated text, not a mind, and apps often show only a summary of it: Claude's API, for example, never returns the raw thinking.
بە ئاستی هەوڵ (effort) ئاڕاستەی دەکەیت. ئاستەکانی Claude ئەمانەن: low، medium، high، xhigh و max: low خێرا و هەرزانە، ئاستە بەرزترەکان لەسەر کێشە قورسەکان زیاتر بیر دەکەنەوە. لەبیرت بێت بیرکردنەوەکە دەقێکی دروستکراوە، نەک مێشک و زۆرجار تەنیا کورتەیەکی نیشان دەدەن: بۆ نموونە Claude هەرگیز بیرکردنەوە خاوەکە ناگەڕێنێتەوە.
Open weights and closed weightsکێشەکانی کراوە و داخراو
A trained model is, at heart, a huge file of numbers: its weights (what a weight is). The company can keep that file secret or publish it.
ڕاهێنراو لە بنەڕەتدا زۆر گەورەی ژمارەیە: (کێش چییە). کۆمپانیاکە دەتوانێت ئەو بە نهێنی بهێڵێتەوە یان بڵاوی بکاتەوە.
- Closed-weight models, such as the biggest Claude, GPT and Gemini models: you use them only through the company's apps or API, on its terms and prices.
- Open-weight models, as of November 2026 for example Mistral Small 4 and Ministral 3 (Apache 2.0), DeepSeek V4.1 Flash and GLM 5.3 (MIT), Meta's Muse Spark Open and OpenAI's gpt-oss (Apache 2.0): anyone may download the weights and run them on their own computer or server, as the licence allows.
- ، وەک گەورەترین Claude، GPT و Gemini: تەنیا لە ڕێگەی یان کۆمپانیاکەوە بەکاریان دەهێنیت، بەپێی مەرج و نرخەکانی.
- ، بەپێی تشرینی دووەمی 2026 بۆ نموونە Mistral Small 4 و Ministral 3 (Apache 2.0)، DeepSeek V4.1 Flash و GLM 5.3 (MIT)، Muse Spark Openـی Meta و gpt-ossـی OpenAI (Apache 2.0): هەر کەسێک دەتوانێت دابار بکات و لەسەر یان خۆی کاریان پێبکات، بەو شێوەیەی ڕێگە دەدات.
Open weights are not the same as open source. Open-source software publishes everything needed to rebuild it (software licences); open-weight models usually keep their training data and training code private, and some licences limit use (Mistral Large 4 has its own open-weight licence).
کراوە واتای نییە. نەرمەواڵەی هەموو ئەوەی بۆ دووپاتە دروستکردنەوەی پێویستە بڵاو دەکاتەوە (مۆڵەتەکانی بەکارهێنان)؛ زۆرجار و کۆدی ڕاهێنانەکەیان بە نهێنی دەهێڵنەوە و هەندێک مۆڵەت بەکارهێنان سنووردار دەکەن (Mistral Large 4 مۆڵەتی تایبەتی خۆی هەیە).
Open weights and closed weightsکێشەکانی کراوە و داخراو
A model on your own machineمۆدێلێک لەسەر ئامێری خۆت
To run an open-weight model yourself, its weights must fit in the memory of your GPU or computer (graphics processors). OpenAI says its gpt-oss-120b runs on a single 80 GB data-centre GPU, while gpt-oss-20b runs within 16 GB of memory.
بۆ ئەوەی خۆت کار پێبکەیت، دەبێت لە یان جێی ببێتەوە (یەکەی چارەسەرکردنی وێنەیی). OpenAI دەڵێت gpt-oss-120bـەکەی لەسەر تەنیا یەک 80 کار دەکات، لە کاتێکدا gpt-oss-20b بە 16 کار دەکات.
Why do it? Privacy (the questions never leave the building), no bill per token, and it works without the internet. The price: you buy and look after the hardware, small models are weaker than the biggest closed ones, and you must update them yourself. A college could, for example, run a small open model on its own server for students' practice questions.
بۆچی؟ (پرسیارەکان هەرگیز لە بیناکە ناچنە دەرەوە)، پارەدان بۆ هەر نییە و بەبێ کار دەکات. نرخەکەی: ئامێرەکە دەکڕیت و ئاگاداری دەبیت، بچووکەکان لە گەورەترین داخراوەکان لاوازترن و دەبێت خۆت نوێیان بکەیتەوە. بۆ نموونە کۆلێژێک دەتوانێت کراوەی بچووک لەسەر خۆی بۆ پرسیارە ڕاهێنانییەکانی قوتابیان کار پێبکات.
Three ways to use a modelسێ ڕێگا بۆ بەکارهێنانی مۆدێلێک
- A chat app in the browser or on your phone: you type and read; free plans or a subscription.
- The API: your program sends a request with the text and gets the answer back; you pay per token. Keep the API key on your server, never inside a phone app or a web page (API keys).
- Locally: an open-weight model on your own machine (previous screen).
- گفتوگۆ لە یان مۆبایلەکەتدا: دەنووسیت و دەخوێنیتەوە؛ پلانی بێبەرانبەر یان .
- API: بە دەقەکەوە دەنێرێت و وەڵامەکە وەردەگرێتەوە؛ بۆ هەر پارە دەدەیت. لەسەر خۆت ڕابگرە، هەرگیز لە ناو مۆبایل یان (کلیلەکانی API).
- بە ناوخۆیی: لەسەر ئامێری خۆت (شاشەی پێشوو).
The data terms can differ: a free chat app, a paid business plan and the API may each treat what you type differently. Read them before you paste anything private (privacy).
مەرجەکانی دەکرێت جیاواز بن: گفتوگۆی بێبەرانبەر، پلانێکی بازرگانیی پارەدار و API دەشێت هەریەکەیان جیاواز مامەڵە لەگەڵ ئەوەدا بکەن کە دەینووسیت. پێش ئەوەی هەر شتێکی تایبەت دابنێیت بیانخوێنەرەوە (تایبەتێتی).
Three ways to use a modelسێ ڕێگا بۆ بەکارهێنانی مۆدێلێک
Same idea, different namesهەمان بیرۆکە، ناوی جیاواز
Every provider's API works the same way: you send a model ID and your text, and you get text back. Only the names differ (from the providers' quick-start pages, November 2026):
هەموو دابینکەرێک هەمان شێوە کار دەکات: و دەقەکەت دەنێریت و دەق وەردەگریتەوە. تەنیا ناوەکان جیاوازن (لە پەڕەکانی دەستپێکردنی دابینکەرانەوە، تشرینی دووەمی 2026):
| Providerدابینکەر | Python package Python | Callبانگکردن | The answer's textدەقی وەڵامەکە | Key variable کلیل |
|---|---|---|---|---|
| Anthropic | anthropic | client.messages.create(model=..., max_tokens=..., messages=[...]) | the text blocks in message.contentبلۆکە دەقییەکانی ناو message.content | ANTHROPIC_API_KEY |
| OpenAI | openai | client.responses.create(model=..., input=...) | response.output_text | OPENAI_API_KEY |
google-genai | client.interactions.create(model=..., input=...) | interaction.output_text | GEMINI_API_KEY |
import anthropic

client = anthropic.Anthropic()        # reads the key from ANTHROPIC_API_KEY

message = client.messages.create(
    model="claude-opus-5-5",
    max_tokens=1024,
    messages=[
        {"role": "user", "content": "Explain RAM to a first-year IT student in three sentences."}
    ],
)

for block in message.content:
    if block.type == "text":
        print(block.text)
Explain the codeڕوونکردنەوەی کۆدەکە
- Lineدێڕی 3
The SDK reads your key from the environment variable, so the key is never written in the code.
کلیلەکەت لە ژینگەوە دەخوێنێتەوە، بۆیە کلیلەکە هەرگیز لە کۆدەکەدا نانووسرێت.
- Lineدێڕی 5-11
Model ID, the longest answer allowed, and the conversation as a list of messages.
، درێژترین وەڵامی ڕێگەپێدراو و گفتوگۆکە وەک نامەکان.
- Lineدێڕی 13-15
The answer comes back as blocks; print the text blocks.
وەڵامەکە وەک چەند بلۆکێک دێتەوە؛ بلۆکە دەقییەکان چاپ بکە.
Choosing a modelهەڵبژاردنی مۆدێلێک
There is no single best model, only the best one for a job. Ask five questions: How hard is the task? Is the Kurdish good enough (test it)? Is the data private (then perhaps a local model)? What is the budget? How fast must it answer?
یەک نییە کە بۆ هەموو کارێک باشترین بێت، تەنیا باشترین بۆ کارێکی دیاریکراو هەیە. پێنج پرسیار بکە: ئەرکەکە چەند قورسە؟ کوردییەکەی بەسە (تاقی بکەرەوە)؟ تایبەتە (کەواتە لەوانەیە ناوخۆیی)؟ بودجە چەندە؟ دەبێت چەند خێرا وەڵام بداتەوە؟
Shilan's helper uses three models: a small one sorts 300 messages a day, a middle one writes polite Kurdish replies, and a big one plans next month's stock once a month. Mixing tiers like this is normal; the cost side is in token optimization.
یاریدەدەرەکەی شیلان سێ بەکار دەهێنێت: بچووکێک ڕۆژانە 300 نامە پۆل دەکات، ناوەندێک وەڵامی کوردیی ڕێکوپێک دەنووسێت و گەورەیەک مانگی یەک جار پلانی کەلوپەلی مانگی داهاتوو دادەنێت. تێکەڵکردنی ئاستەکان بەم شێوەیە ئاساییە؛ لایەنی تێچووەکەی لە باشترینکردنی تۆکنـدایە.
Choosing a modelهەڵبژاردنی مۆدێلێک
Choosing in Pythonهەڵبژاردن بە Python
Karwan keeps the models in a list of dictionaries and lets a function pick one for each job. The numbers are the November 2026 examples from the table.
کاروان لە هەڵدەگرێت و بۆ هەر کارێک یەکێکیان هەڵدەبژێرێت. ژمارەکان نموونەکانی تشرینی دووەمی 2026ن لە خشتەکەوە.
# Example numbers from the providers' model pages, checked in November 2026.
# Prices: US dollars per million tokens. They change often: check again!
MODELS = [
    {"name": "Claude Fable 5.2",  "tier": "big",    "context": 1_000_000, "price_in": 8.00,  "price_out": 40.00},
    {"name": "Claude Opus 5.5",   "tier": "middle", "context": 1_000_000, "price_in": 4.00,  "price_out": 20.00},
    {"name": "Claude Sonnet 5.5", "tier": "middle", "context": 1_000_000, "price_in": 2.00,  "price_out": 10.00},
    {"name": "Claude Haiku 5.5",  "tier": "small",  "context": 1_000_000, "price_in": 0.10,  "price_out": 0.50},  # prompts up to 100,000 tokens
    {"name": "GPT-6 Astra",       "tier": "big",    "context": 1_050_000, "price_in": 10.00, "price_out": 50.00},
    {"name": "GPT-6.1 Sol",       "tier": "middle", "context": 1_050_000, "price_in": 2.00,  "price_out": 10.00},
    {"name": "GPT-6 Luna",        "tier": "small",  "context": 1_050_000, "price_in": 0.10,  "price_out": 0.50},
    {"name": "Gemini 3.8 Flash",  "tier": "middle", "context": 1_048_576, "price_in": 0.75,  "price_out": 3.75},
]


def choose(models, tiers, need_context, max_price_out):
    """Return the cheapest model that fits, or None."""
    best = None
    for m in models:
        if m["tier"] not in tiers:
            continue
        if m["context"] < need_context or m["price_out"] > max_price_out:
            continue
        if best is None or m["price_out"] < best["price_out"]:
            best = m
    return best


jobs = [
    ("Sort customer messages", ["small"], 5_000, 1.00),
    ("Write polite replies", ["middle", "big"], 20_000, 12.00),
    ("Plan next month's stock", ["big"], 300_000, 45.00),
    ("Read a 1.2-million-token archive", ["small", "middle", "big"], 1_200_000, 50.00),
]

for job, tiers, need, max_out in jobs:
    m = choose(MODELS, tiers, need, max_out)
    if m is None:
        print(f"{job}: no model fits")
    else:
print(f"{job}: {m['name']} (${m['price_in']:.2f} in, ${m['price_out']:.2f} out)")Sort customer messages: Claude Haiku 5.5 ($0.10 in, $0.50 out) Write polite replies: Gemini 3.8 Flash ($0.75 in, $3.75 out) Plan next month's stock: Claude Fable 5.2 ($8.00 in, $40.00 out) Read a 1.2-million-token archive: no model fits
Explain the codeڕوونکردنەوەی کۆدەکە
- Lineدێڕی 3-13
Each model is a dictionary; the keys must be spelt the same in every one.
هەر ؛ دەبێت لە هەموویاندا وەک یەک بنووسرێن.
- Lineدێڕی 21
Skip a model whose context window is too small or whose output price is over the budget.
ئەو بپەڕێنە کە بچووکە یان نرخی لە بودجە زیاترە.
- Lineدێڕی 23
Keep the cheapest so far. On a tie (Haiku 5.5 and Luna) the first one in the list stays, because
<is strict.تا ئێستا هەرزانترین هەڵبگرە. لە یەکسانبووندا (Haiku 5.5 و Luna) یەکەمیان لە لیستەکەدا دەمێنێتەوە، چونکە
<توندە.- Lineدێڕی 37-40
Nonemeans no model passed every check.Noneواتە هیچ لە هەموو پشکنینەکان دەرنەچوو.
Testing the claims yourselfتاقیکردنەوەی بانگەشەکان بە خۆت
Adverts and public leaderboards rank models on shared tests, mostly in English and on tasks that are not yours. Before you choose, run your own evaluation: write 20 real questions from your work, in Kurdish if you will use Kurdish, with the good answers you expect. Ask every candidate model the same questions, score the answers and compare.
ڕیکلام و خشتە گشتییەکانی پلەبەندی لەسەر تاقیکردنەوەی هاوبەش ڕیز دەکەن، زۆربەیان بە ئینگلیزی و لەسەر ئەرکی کەسانی تر. پێش ئەوەی هەڵبژێریت، ی خۆت بکە: 20 پرسیاری ڕاستەقینە لە کارەکەتەوە بنووسە، بە کوردی ئەگەر کوردی بەکار دەهێنیت، لەگەڵ ئەو وەڵامە باشانەی چاوەڕێیان دەکەیت. هەمان پرسیار لە هەموو کاندیدەکان بکە، نمرە بە وەڵامەکان بدە و بەراوردیان بکە.
Keep the questions and test again whenever a model is updated or retired. The same habit works for prompts: test your prompt.
پرسیارەکان هەڵبگرە و هەر کاتێک نوێ کرایەوە یان خانەنشین کرا دیسان تاقی بکەرەوە. هەمان خوو بۆ کار دەکات: هەوێنەکەت تاقی بکەرەوە.
Common mistakesهەڵە باوەکان
A mistake in the code: one misspelt key. Line 21 was typed with price-out instead of price_out:
هەڵەیەک لە کۆدەکەدا: هەڵە نووسراو. دێڕی 21 بە price-out لە جیاتی price_out نووسرابوو:
if m["context"] < need_context or m["price-out"] > max_price_out:Traceback (most recent call last):
File "choose_model.py", line 36, in <module>
m = choose(MODELS, tiers, need, max_out)
File "choose_model.py", line 21, in choose
if m["context"] < need_context or m["price-out"] > max_price_out:
~^^^^^^^^^^^^^
KeyError: 'price-out'Dictionary keys must match letter for letter, so Python stops with a KeyError. Fix: copy the key exactly (m["price_out"]). When a key may really be missing, m.get("price_out") returns None instead of stopping, and your code must then decide what to do with None.
دەبێت پیت بە پیت وەک یەک بن، بۆیە Python بە KeyError دەوەستێت. چارەسەر: کلیلەکە ڕێک کۆپی بکە (m["price_out"]). کاتێک دەکرێت کلیلێک بەڕاستی نەبێت، m.get("price_out") لە جیاتی وەستان None دەگەڕێنێتەوە و ئینجا کۆدەکەت دەبێت بڕیار بدات چی لە None بکات.
Exercisesڕاهێنانەکان
Put each name in its layer (company, model or product): Anthropic, ChatGPT, Gemini 3.8 Flash, Google, the Claude app, GPT-6.1 Sol, OpenAI.
هەر ناوێک لە چینەکەی خۆیدا دابنێ (کۆمپانیا، یان بەرهەم): Anthropic، ChatGPT، Gemini 3.8 Flash، Google، Claude، GPT-6.1 Sol، OpenAI.
Show answerوەڵامەکە پیشان بدە
Company: Anthropic, Google, OpenAI. Model: Gemini 3.8 Flash, GPT-6.1 Sol. Product: ChatGPT, the Claude app.
کۆمپانیا: Anthropic، Google، OpenAI. : Gemini 3.8 Flash، GPT-6.1 Sol. بەرهەم: ChatGPT، Claude.
Choose big, middle or small and say why: (a) tag 10,000 product reviews as positive or negative; (b) plan a two-week school timetable with many rules; (c) answer customers in polite Kurdish; (d) suggest a title for a blog post.
گەورە، ناوەند یان بچووک هەڵبژێرە و بڵێ بۆچی: (a) 10,000 ڕاوبۆچوونی کڕیار وەک ئەرێنی یان نەرێنی نیشان بکە؛ (b) خشتەی وانەکانی دوو هەفتەی قوتابخانەیەک بە یاسای زۆرەوە دابنێ؛ (c) بە کوردییەکی ڕێکوپێک وەڵامی کڕیاران بدەرەوە؛ (d) ناونیشانێک بۆ بابەتێکی بلۆگ پێشنیار بکە.
Show answerوەڵامەکە پیشان بدە
(a) Small: an easy, repeated label. (b) Big, a reasoning model at higher effort: many rules to satisfy at once. (c) Middle, after you test its Kurdish on real messages. (d) Small or middle: a short creative task. In every case, test on a few real examples first.
(a) بچووک: ئاسان و دووپاتە. (b) گەورە، بە هەوڵی بەرزتر: زۆر یاسا هەن کە دەبێت پێکەوە جێبەجێ بن. (c) ناوەند، دوای ئەوەی کوردییەکەی لەسەر نامەی ڕاستەقینە تاقی دەکەیتەوە. (d) بچووک یان ناوەند: ئەرکێکی داهێنانیی کورت. لە هەموو حاڵەتێکدا سەرەتا لەسەر چەند نموونەیەکی ڕاستەقینە تاقی بکەرەوە.
Use the November 2026 table: (a) Which smallest models are the cheapest? (b) Does a 200,000-token request fit in Gemini 4 Argon's context window? (c) What happens to Gemini 4 Argon's price on 1 December 2026?
خشتەکەی تشرینی دووەمی 2026 بەکار بهێنە: (a) کام بچووکترین هەرزانترینن؟ (b) 200,000 لە Gemini 4 Argonـدا جێی دەبێتەوە؟ (c) لە 1ی کانوونی یەکەمی 2026دا چی بە نرخی Gemini 4 Argon دێت؟
Show answerوەڵامەکە پیشان بدە
(a) Claude Haiku 5.5 and GPT-6 Luna, both $0.10 input and $0.50 output per million tokens. (b) Yes: its window is 1,048,576 tokens, and the answer must fit in it too. (c) It doubles, from $2 / $10 to $4 / $20 per million tokens.
(a) Claude Haiku 5.5 و GPT-6 Luna، هەردووکیان $0.10 بۆ و $0.50 بۆ بۆ هەر ملیۆن . (b) بەڵێ: پەنجەرەکەی 1,048,576 و وەڵامەکەش دەبێت تێیدا جێی ببێتەوە. (c) دوو هێندە دەبێت، لە $2 / $10ـەوە بۆ $4 / $20 بۆ هەر ملیۆن .
Add GPT-6.1 Terra (middle tier, 1,050,000 tokens, $1.00 input, $5.00 output) to MODELS in choose_model.py. Which model does “Write polite replies” choose now, and why?
GPT-6.1 Terra (ئاستی ناوەند، 1,050,000 ، $1.00 ، $5.00 ) بۆ MODELS لە choose_model.pyـدا زیاد بکە. ئێستا «Write polite replies» کام هەڵدەبژێرێت و بۆچی؟
Show answerوەڵامەکە پیشان بدە
{"name": "GPT-6.1 Terra", "tier": "middle", "context": 1_050_000, "price_in": 1.00, "price_out": 5.00},Sort customer messages: Claude Haiku 5.5 ($0.10 in, $0.50 out) Write polite replies: Gemini 3.8 Flash ($0.75 in, $3.75 out) Plan next month's stock: Claude Fable 5.2 ($8.00 in, $40.00 out) Read a 1.2-million-token archive: no model fits
Nothing changes: Gemini 3.8 Flash is still chosen, because its output price ($3.75) is lower than Terra's ($5.00). Run it and see the same four lines.
هیچ ناگۆڕێت: هێشتا Gemini 3.8 Flash هەڵدەبژێردرێت، چونکە نرخی ($3.75) لە هی Terra ($5.00) کەمترە. کاری پێبکە و هەمان چوار دێڕ دەبینیت.
Summaryپوختە
- Three layers: a company trains a model, which you reach through a product (a chat app or the API).
- Families come in tiers: big for hard reasoning, middle for most work, small (a small language model) for fast, cheap, simple jobs.
- A model page shows the ID, context window, max output, knowledge cutoff, price per million tokens and retirement date.
- After the knowledge cutoff a model knows nothing unless an app gives it fresh text.
- Reasoning models think before answering: better at hard problems, slower, and the thinking is billed as output.
- Open-weight models can be downloaded and run locally (not the same as open source); closed-weight models only through the company.
- Choose by task, Kurdish quality, privacy, budget and speed, and test with your own questions; names and prices change, so check the providers' pages.
- سێ چین: کۆمپانیایەک ڕادەهێنێت کە لە ڕێگەی بەرهەمێکەوە دەیگەیتێ ( گفتوگۆ یان API).
- خێزانەکان بە ئاست دێن: گەورە بۆ بیرکردنەوەی قورس، ناوەند بۆ زۆربەی کار، بچووک () بۆ کاری خێرا، هەرزان و سادە.
- پەڕەی ، ، زۆرترین ، ، نرخ بۆ هەر ملیۆن و ڕێکەوتی خانەنشینی نیشان دەدات.
- دوای هیچ نازانێت، مەگەر دەقی نوێی پێبدات.
- پێش وەڵامدانەوە بیر دەکەنەوە: لە کێشە قورسەکاندا باشترن، هێواشترن و بیرکردنەوەکە وەک پارەی لێ وەردەگیرێت.
- دابار دەکرێن و بە ناوخۆیی کاریان پێدەکرێت ( نییە)؛ تەنیا لە ڕێگەی کۆمپانیاکەوە.
- بەپێی ئەرک، کوالیتیی کوردی، ، بودجە و خێرایی هەڵبژێرە و بە پرسیارەکانی خۆت تاقی بکەرەوە؛ ناو و نرخەکان دەگۆڕێن، بۆیە پەڕەکانی دابینکەران بپشکنە.
Next: what happens inside when a model writes, token by token: How a language model writes.
داهاتوو: کاتێک بە دەنووسێت، لە ناوەوە چی ڕوو دەدات: مۆدێلێکی زمان چۆن دەنووسێت.
Lesson complete!وانەکە تەواو بوو!
Well done. Review the key terms, then go on to the next lesson.دەستخۆش. سەیرێکی زاراوە سەرەکییەکان بکەرەوە، پاشان بڕۆ بۆ وانەی داهاتوو.
Key termsزاراوە سەرەکییەکان
How a Language Model Writes: Tokens, Probabilities and the Context Windowمۆدێلی زمان چۆن دەنووسێت: تۆکنەکان، ئەگەرەکان و پەنجەرەی کۆنتێکست
Related lecturesوانە پەیوەندیدارەکان
- Web APIs and JSONAPIـی وێب و JSON
- Cloud Computingهەورەژمێرکاری
- Processor Speed, Cache, GPUs and Coolingخێرایی پرۆسێسەر، کاش، GPU و ساردکردنەوە
- Intellectual Property, Plagiarism and Software Licencesموڵکی هزری، دزیی زانستی و مۆڵەتەکانی بەکارهێنان
- Neural Networks and Deep Learningتۆڕە دەمارییەکان و فێربوونی قووڵ
- Can Machines Think? The Turing Testئایا ئامێرەکان بیر دەکەنەوە؟ تاقیکاریی تیورینگ
- Tuples, Sets and Dictionariesتاپڵەکان، کۆمەڵەکان و فەرهەنگەکان
References and further readingسەرچاوەکان و خوێندنەوەی زیاتر
- Anthropic: Models overview (Claude Fable 5.2, Opus 5.5, Sonnet 5.5, Haiku 5.5; context, max output, cutoffs, retirement), checked 10 November 2026
- Anthropic: Pricing (per-million-token prices; Haiku 5.5 prompt-length pricing; batch discount), checked 10 November 2026
- Anthropic: Thinking (adaptive thinking, summarized thinking, thinking billed as output tokens)
- Anthropic: Effort (low, medium, high, xhigh, max)
- Anthropic: Get started with Claude (Python SDK first request, ANTHROPIC_API_KEY)
- OpenAI API: Models (GPT-6 Astra, GPT-6.1 Sol, GPT-6.1 Terra, GPT-6 Luna; context, cutoffs, prices, reasoning levels), checked 10 November 2026
- OpenAI API: Quickstart (responses.create, output_text, OPENAI_API_KEY)
- OpenAI: gpt-oss on GitHub (open-weight gpt-oss-120b and gpt-oss-20b, Apache 2.0, memory needs)
- Google AI Studio: Gemini models (Gemini 4 Argon, 3.8 Flash, 3.5 Flash-Lite; deprecations), checked 10 November 2026
- Google AI Studio: Gemini 4 Argon model page (1,048,576-token context window)
- Google AI Studio: Gemini 3.8 Flash model page (inputs, thinking levels)
- Google AI Studio: Gemini API pricing (thinking tokens included in output price; Argon price change on 1 December 2026)
- Google AI Studio: Quickstart (interactions.create, output_text, GEMINI_API_KEY)
- Mistral AI: Models overview (open-weight models and licences; hosted DeepSeek and GLM)
- Meta: AI developer page (Muse Spark Open, an open-weight model)
- Wikipedia: OpenAI o1 (o1-preview released 12 September 2024)
- Python documentation: Mapping types, dict (KeyError and dict.get)
This lecture is a first edition. The Kurdish text and terminology are waiting for review by Kurdish IT teachers.ئەم وانەیە چاپی یەکەمە. دەقە کوردییەکە و زاراوەکانی چاوەڕێی پێداچوونەوەی مامۆستایانی کوردی بواری IT ن.