Chapterبەش 7 · Lectureوانە 7.1
How Search Engines Workبزوێنەرەکانی گەڕان چۆن کار دەکەن
What a search engine really searches (its index, not the live Web) and why we need one; the three parts — crawler, index and ranking software; crawling, indexing and serving step by step with a tiny inverted index, robots.txt and sitemaps; the crawl loop as an animation; kinds of search (general, specialised, image, reverse-image, video; crawler, directory, hybrid and semantic indexes); reading a results page; SEO and its benefits; and which famous engines are gone.
لە ڕاستیدا لە چی دەگەڕێت (، نەک زیندوو) و بۆچی پێویستمانە؛ سێ بەشەکەی — ، و ڕیزبەندی؛ خشاندن، پێڕستکردن و پێشکەشکردن هەنگاو بە هەنگاو لەگەڵ نموونەیەکی بچووکی ، robots.txt و ؛ خولی خشاندن وەک جوڵەوێنە؛ جۆرەکانی گەڕان (گشتی، تایبەت، وێنە، پێچەوانە بە وێنە، ڤیدیۆ؛ ، ، تێکەڵ و واتایی)؛ خوێندنەوەی لاپەڕەی ئەنجامەکان؛ و سوودەکانی؛ و ئەوەی کام لە ناوە بەناوبانگەکان نەماون.
What you will learnچی فێر دەبیت
- Explain why a search engine answers from its index and not from the live Web.
- Name the three parts of a search engine and the three stages crawl, index, serve.
- Build a small inverted index and answer a search with it.
- Describe the crawl loop and what robots.txt and sitemaps do (and do not do).
- Tell adverts from organic results on a results page and name the kinds of search engine.
- List good SEO practices and the benefits of SEO for a website and a business.
- ڕوون بکەیتەوە بۆچی لە وەڵام دەداتەوە نەک لە زیندووەوە.
- سێ بەشەکەی و سێ قۆناغەکەی خشاندن، پێڕستکردن و پێشکەشکردن ناو ببەیت.
- نموونەیەکی بچووکی دروست بکەیت و گەڕانێکی پێ وەڵام بدەیتەوە.
- خولی خشاندن وەسف بکەیت و ئەوەی robots.txt و دەیکەن (و نایکەن).
- لە لاپەڕەی ئەنجامەکاندا ڕیکلام لە جیا بکەیتەوە و جۆرەکانی ناو ببەیت.
- ڕێگە باشەکانی و سوودەکانی بۆ و بازرگانییەک ڕیز بکەیت.
What a search engine really searchesبزوێنەری گەڕان لە ڕاستیدا لە کوێ دەگەڕێت؟
A search engine is a website, and the huge system behind it, that finds web pages for the words you type. Google, Bing, Baidu, Yandex and DuckDuckGo are search engines. You type a few words — a search term — and a list of pages comes back in less than a second.
لەگەڵ سیستەمێکی زۆر گەورە لە پشتییەوە، کە بۆ ئەو وشانەی دەینووسیت دەدۆزێتەوە. Google، Bing، Baidu، Yandex و DuckDuckGo . چەند وشەیەک دەنووسیت — — و لە کەمتر لە چرکەیەکدا لیستێکی لاپەڕە دەگەڕێتەوە.
How can it be so fast? Because when you press Enter, the search engine does not go out and read the Web. Long before your search, it collected information about billions of pages, indexed it (made a word list of it, like the index at the back of a book) and stored the result in a huge database built for quick lookups — the search index. The search box and the results page are only the interface to that database. Your search is answered from the index, not from the live Web.
چۆن ئەوەندە خێرایە؟ چونکە کاتێک Enter دادەگریت، ناچێتە دەرەوە بۆ خوێندنەوەی . زۆر پێش گەڕانەکەی تۆ، زانیاریی دەربارەی ملیارەها لاپەڕە کۆ کردووەتەوە، پێڕستی بۆ دروست کردوون (لیستێکی وشەی لێ دروست کردوون، وەک پێڕستی کۆتایی کتێب) و ئەنجامەکەی لە زۆر گەورەدا هەڵگرتووە کە بۆ دۆزینەوەی خێرا دروست کراوە — . خانەی گەڕان و لاپەڕەی ئەنجامەکان تەنها ڕووکارێکن بۆ ئەو . گەڕانەکەت لە وەڵام دەدرێتەوە، نەک لە زیندووەوە.
The huge in which a keeps what it has learned about every it collected: the words, where they appear and many other signals. Your search is answered from this index, not from the live Web.
ئەو گەورەیەی زانیارییەکانی هەر تێدا هەڵدەگرێت کە کۆی کردووەتەوە: وشەکان، شوێنی وشەکان و زۆر نیشانەی تر. گەڕانەکەت لەم پێڕستەوە وەڵام دەدرێتەوە، نەک لە زیندووەوە.
What a search engine really searchesبزوێنەری گەڕان لە ڕاستیدا لە کوێ دەگەڕێت؟
Like a library catalogueوەک کەتەلۆگی کتێبخانە
Ask the university librarian for books about dams. She does not walk along every shelf: she looks in the catalogue, a list that says which shelf holds which book, and answers in a moment. A search engine works the same way: its spider walked the shelves earlier and wrote the catalogue, and your question is answered from the catalogue.
داوای کتێب دەربارەی بەنداو لە کتێبدارەکەی زانکۆ بکە. بەلای هەموو ڕەفەکاندا ناڕوات: سەیری کەتەلۆگ دەکات، لیستێک کە دەڵێت کام کتێب لەسەر کام ڕەفە و لە ساتێکدا وەڵام دەداتەوە. بە هەمان شێوە کار دەکات: پێشتر بەسەر ڕەفەکاندا گەڕاوە و کەتەلۆگەکەی نووسیوە و پرسیارەکەت لە کەتەلۆگەکەوە وەڵام دەدرێتەوە.
Where the analogy stops workingسنووری ئەم نموونەیە
A book put on a shelf this morning is not in the catalogue until someone adds it — and a page published five minutes ago is usually not in the index yet. The Web also changes far faster than a library, so the spider has to come back again and again.
کتێبێک کە ئەمڕۆ بەیانی خراوەتە سەر ڕەفە تا کەسێک زیادی نەکات لە کەتەلۆگدا نییە — و لاپەڕەیەکیش کە پێنج خولەک لەمەوبەر بڵاو کراوەتەوە زۆرجار هێشتا لە نییە. زۆر خێراتر لە کتێبخانە دەگۆڕێت، بۆیە دەبێت چەندین جار بگەڕێتەوە.
Why we need search enginesبۆچی پێویستمان بە بزوێنەرەکانی گەڕان هەیە؟
The Web has no table of contents. There is no central list of all web pages, and anyone can publish a new page at any moment. Without search engines you could only reach pages whose address you already knew, or follow links by luck. Search engines help in three ways:
نییە. هیچ لیستێکی ناوەندیی هەموو نییە و هەر کەسێک دەتوانێت لە هەر ساتێکدا لاپەڕەیەکی نوێ بڵاو بکاتەوە. بەبێ تەنها دەگەیشتیت بەو لاپەڕانەی پێشتر دەزانی، یان بە بەخت بەدوای دەچوویت. بە سێ ڕێگە یارمەتی دەدەن:
| Needپێویستی | What the search engine gives youئەوەی پێت دەدات | Example: «dams in Kurdistan»نموونە: «بەنداوەکانی کوردستان» |
|---|---|---|
| Varietyجۆراوجۆری | Many kinds of sources for one question, so you choose the kinds you trust or combine several to understand the subject better.چەندین جۆری سەرچاوە بۆ یەک پرسیار، بۆیە ئەو جۆرانە هەڵدەبژێریت کە متمانەت پێیانە، یان چەند دانەیەک پێکەوە بەکار دەهێنیت بۆ ئەوەی باشتر لە بابەتەکە تێبگەیت. | News reports, a ministry page, an encyclopedia article, a video, a PDF study and a map.هەواڵ، لاپەڕەی وەزارەتێک، وتارێکی ئینسایکلۆپیدیا، ڤیدیۆیەک، توێژینەوەیەکی PDF و نەخشەیەک. |
| Organisationڕێکخستن | Millions of matching pages become one ordered list, best first; one site's main sections appear as links under its result.ملیۆنەها لاپەڕەی گونجاو دەبنە یەک لیستی ڕیزکراو، باشترینەکەیان یەکەم؛ بەشە سەرەکییەکانی تۆڕگەیەک وەک بەستەر لە ژێر ئەنجامەکەیدا دەردەکەون. | The Dukan and Darbandikhan dam pages come before a forum post from 2009.لاپەڕەکانی بەنداوی دوکان و دەربەندیخان پێش پۆستێکی کۆڕێکی ئۆنلاینی ساڵی 2009 دێن. |
| Precisionوردی | You can refine the search to get fewer, more exact results: more words, exact phrases, a date, Images or News only.دەتوانیت گەڕانەکە وردتر بکەیت بۆ ئەوەی ئەنجامی کەمتر و وردتر وەربگریت: وشەی زیاتر، دەستەواژەی تەواو، بەروارێک، تەنها Images یان News. | «Darbandikhan dam» water level 2026 filetype:pdf |
The three parts of a search engineسێ بەشەکەی بزوێنەری گەڕان
Every search engine is built from three parts that work one after another:
هەموو لە سێ بەش دروست بووە کە یەک لە دوای یەک کار دەکەن:
| Partبەش | What it doesچی دەکات |
|---|---|
| 1. The spider (also called crawler or robot)1. (پێی دەوترێت spider یان robotـیش) | A program that tracks down web pages. It downloads a page, follows the links on it to more pages, and adds what it finds to the search engine's database. Google's is called Googlebot. کە بەدوای دەگەڕێت. لاپەڕەیەک دادەبەزێنێت، بەدوای ناوییدا دەچێت بۆ لاپەڕەی زیاتر و ئەوەی دەیدۆزێتەوە دەیخاتە ناو . هی Google ناوی Googlebotـە. |
| 2. The index2. بەشی | The database that holds a copy of each page the spider gathered, turned into a word list that can be searched in an instant.ئەو کۆپییەکی هەر لاپەڕەیەکی تێدایە کە کۆی کردووەتەوە، کراوە بە لیستێکی وشە کە دەکرێت لە ساتێکدا تێیدا بگەڕێیت. |
| 3. The search software3. گەڕان | The program that takes your search term, looks it up in the index and returns the matching pages in ranked order: the most useful first.ئەو وەردەگرێت، لە بەدوایدا دەگەڕێت و لاپەڕە گونجاوەکان بە ڕیزبەندی دەگەڕێنێتەوە: بەسوودترین یەکەم. |
The three parts of a search engineسێ بەشەکەی بزوێنەری گەڕان
The web crawler and its many namesخشۆکی وێب و ناوە زۆرەکانی
A web crawler is a program that browses the World Wide Web in a methodical, automated way: no person clicks, the program itself downloads pages and follows their links, day and night. Because it «walks» the web of links, people gave it many names:
کە بە شێوەیەکی ڕێکخراو و خۆکار بە دەگەڕێت: هیچ مرۆڤێک ناکات، خۆی لاپەڕەکان دادەبەزێنێت و بەدوای دەچێت، شەو و ڕۆژ. چونکە بەسەر تۆڕی «دەڕوات»، خەڵک چەندین ناویان لێ ناوە:
A program that visits web pages automatically, follows their links and collects their content, for example so that a search engine can show them in its results.
کە بە شێوەیەکی خۆکار سەردانی دەکات، بەدوای بەستەرەکانیاندا دەڕوات و ناوەڕۆکیان کۆ دەکاتەوە، بۆ نموونە بۆ ئەوەی لە ئەنجامەکانیدا پیشانیان بدات.
| English nameناوی ئینگلیزی | Whyبۆچی |
|---|---|
| crawler | It crawls slowly and steadily from page to page.بە هێواشی و بەردەوامی لە لاپەڕەیەکەوە بۆ لاپەڕەیەکی تر دەخشێت. |
| spider | The Web is a «web» of links, and a spider walks along its web. «تۆڕ»ێکی و جاڵجاڵۆکە بەسەر تۆڕەکەیدا دەڕوات. |
| robot, bot | It works by itself, like a machine; Googlebot and Bingbot carry the word in their names.خۆی کار دەکات، وەک ئامێرێک؛ Googlebot و Bingbot ئەم وشەیەیان لە ناوەکەیاندایە. |
| web agent | It acts for its owner on the Web, like the software agents of the AI course.لە بۆ خاوەنەکەی کار دەکات، وەک کۆرسی . |
| wanderer, worm | Old names from the early 1990s.ناوی کۆن لە سەرەتای ساڵانی 1990. |
Examples: Googlebot (Google) and Bingbot (Microsoft Bing). Crawlers are not only for search: link checkers, price-comparison sites, web archives and the companies that train AI models run crawlers too. In the AI course they appear as internet software agents.
نموونە: Googlebot (Google) و Bingbot (Bingـی Microsoft). تەنها بۆ گەڕان نین: پشکنەری ، تۆڕگەکانی بەراوردکردنی نرخ، ئەرشیفەکانی و ئەو کۆمپانیایانەی مۆدێلی ڕادەهێنن، بەکار دەهێنن. لە کۆرسی وەک ئەیجێنتە نەرمەواڵەییەکانی ئینتەرنێت دەردەکەون.
How Google finds pages: URL discovery, what Googlebot is, fetching and rendering, and how sitemaps help the crawler.
Google چۆن دەدۆزێتەوە: ناسینی نوێیەکان، Googlebot چییە، و لاپەڕەکان؛ هەروەها چۆن یارمەتی دەدەن.
Whole video (6:49), Google Search Central: crawling, Googlebot and sitemaps.
هەموو ڤیدیۆکە (6:49)، Google Search Central: گەڕان بە ناو (crawling)، Googlebot و .
Crawl, index, serve: step by stepخشاندن، پێڕستکردن، پێشکەشکردن: هەنگاو بە هەنگاو
Google describes its work in three stages, and every big search engine works the same way. Not every page passes all three: some are never found, some are found but not indexed, and some are indexed but rarely shown.
Google کارەکەی بە سێ قۆناغ وەسف دەکات و هەموو گەورە بە هەمان شێوە کار دەکات. هەموو لاپەڕەیەک بە هەر سێ قۆناغەکەدا تێناپەڕێت: هەندێکیان هەرگیز نادۆزرێنەوە، هەندێکیان دەدۆزرێنەوە بەڵام ناخرێنە ناو و هەندێکیان دەخرێنە ناوی بەڵام کەم پیشان دەدرێن.
1 Crawling: find and download pages. There is no central list of all pages, so the crawler keeps discovering URLs: it revisits pages it already knows, follows their links to new pages, and reads sitemaps that site owners send in. It downloads the text, pictures and videos and runs the page like a browser does. A program decides which sites to visit, how often and how many pages to take; if a site's server answers slowly or with errors, the crawler slows down. Pages blocked by robots.txt or hidden behind a login are skipped.
1 خشاندن: دۆزینەوە و دابەزاندنی لاپەڕەکان. هیچ لیستێکی ناوەندیی هەموو لاپەڕەکان نییە، بۆیە بەردەوام دەدۆزێتەوە: دەگەڕێتەوە سەر ئەو لاپەڕانەی پێشتر دەیانناسێت، بەدوای دەچێت بۆ لاپەڕەی نوێ و دەخوێنێتەوە کە خاوەنی تۆڕگەکان دەینێرن. دەق، وێنە و ڤیدیۆکان دادەبەزێنێت و لاپەڕەکە وەک دەکاتەوە. بڕیار دەدات سەردانی کام بکات، چەند جار و چەند لاپەڕە ببات؛ ئەگەر تۆڕگەیەک هێواش یان بە هەڵە وەڵام بداتەوە، خێرایی خۆی کەم دەکاتەوە. ئەو لاپەڕانەی بە robots.txt ڕێگەیان لێ گیراوە یان پێویستیان بە هەیە بەجێ دەهێڵرێن.
Crawl, index, serve: step by stepخشاندن، پێڕستکردن، پێشکەشکردن: هەنگاو بە هەنگاو
Indexing and servingپێڕستکردن و پێشکەشکردن
2 Indexing: understand and store. The engine builds a list of the words on the page and notes where each was found — in the title, a heading, the body, the text of a link, the alt text of a picture. It gives each word its own weight: a word in the title counts more than the same word in the footer. It groups copies of the same page and keeps one main version, and notes signals such as the language, the country and whether the page works on phones. Finally it encodes and compresses the data to save space and stores it across thousands of computers, ready for users.
2 پێڕستکردن: تێگەیشتن و هەڵگرتن. لیستێک لە وشەکانی لاپەڕەکە دروست دەکات و دەنووسێت هەر وشەیەک لە کوێ دۆزراوەتەوە — لە ناونیشان، سەردێڕێک، ناوەڕۆک، دەقی ، وێنەیەک. قورساییی تایبەت بە هەر وشەیەک دەدات: وشەیەک لە ناونیشاندا لە هەمان وشە لە گرنگترە. کۆپییەکانی هەمان لاپەڕە کۆ دەکاتەوە و یەک وەشانی سەرەکی هەڵدەگرێت و نیشانەکانی وەک زمان، وڵات و ئەوەی ئایا لاپەڕەکە لەسەر مۆبایل کار دەکات تۆمار دەکات. لە کۆتاییدا دراوەکان کۆد دەکات و دەیانپەستێنێت بۆ پاشەکەوتکردنی شوێن و لەسەر هەزارەها هەڵیان دەگرێت، ئامادە بۆ .
3 Serving: answer a search. When you search, the software looks up your words in the index, finds the matching pages and ranks them by relevance and quality, using hundreds of signals that include your language, your location and your device. A search for «bus to Duhok» in Erbil and in Zakho gives different results.
3 پێشکەشکردن: وەڵامدانەوەی گەڕانێک. کاتێک دەگەڕێیت، وشەکانت لە دەدۆزێتەوە، لاپەڕە گونجاوەکان دەدۆزێتەوە و بەپێی گونجان و کوالیتی ڕیزیان دەکات، بە بەکارهێنانی سەدان نیشانە کە زمانەکەت، شوێنەکەت و ئامێرەکەت لەخۆ دەگرن. گەڕان بۆ «پاس بۆ دهۆک» لە هەولێر و لە زاخۆ ئەنجامی جیاواز دەدات.
What happens after crawling: Google reads the words and tags of a page, picks one version of duplicate pages and stores it in the index.
دوای ئەوەی لاپەڕەیەک دەدۆزێتەوە: Google وشە و لاپەڕەکە دەخوێنێتەوە، یەک دانە لە لاپەڕە دووبارەکان هەڵدەبژێرێت و لە هەڵیدەگرێت.
Plays 0:00-2:26: how Google reads a page's text, tags, images and video to build its index. The canonical-page and index-selection parts are left out.
لە 0:00 تا 2:26 پەخش دەبێت: Google چۆن دەق، ، وێنە و ڤیدیۆی لاپەڕەیەک دەخوێنێتەوە بۆ دروستکردنی . بەشەکانی لاپەڕەی بنەڕەتی (canonical) و هەڵبژاردن بۆ لابراون.
Crawl, index, serve: step by stepخشاندن، پێڕستکردن، پێشکەشکردن: هەنگاو بە هەنگاو
Inside the index: an inverted indexلە ناو پێڕستی گەڕاندا: پێڕستی پێچەوانە
Imagine the whole Web had only three tiny pages. Reading all three for every search would be slow on the real Web, so the engine builds the list the other way round: for each word, the pages that contain it. This is an inverted index, exactly like the index at the back of a textbook that sends you from a word to its page numbers.
وا دابنێ هەموو تەنها سێ لاپەڕەی بچووکی هەبێت. خوێندنەوەی هەر سێکیان بۆ هەموو گەڕانێک لە ڕاستەقینەدا هێواش دەبێت، بۆیە لیستەکە بە پێچەوانەوە دروست دەکات: بۆ هەر وشەیەک، ئەو لاپەڕانەی ئەو وشەیەیان تێدایە. ئەمە ، ڕێک وەک پێڕستی کۆتایی کتێبی خوێندن کە لە وشەیەکەوە دەتباتە سەر ژمارەی لاپەڕەکانی.
A search for two words reads two rows and keeps the pages that are in both. Real indexes also store the position of each word, so a search for the exact phrase «Erbil citadel» can check that the two words stand side by side, and the weight of each place, so a page with the word in its title can rank higher. Google says its index works like «the index in the back of a book», holds hundreds of billions of pages and is well over 100,000,000 gigabytes.
گەڕان بە دوو وشە دوو ڕیز دەخوێنێتەوە و ئەو لاپەڕانە دەهێڵێتەوە کە لە هەردووکیاندا هەن. لە ڕاستیدا شوێنی هەر وشەیەکیش هەڵدەگرن، بۆ ئەوەی گەڕان بۆ دەستەواژەی تەواوی «قەڵای هەولێر» بپشکنێت کە دوو وشەکە لە تەنیشت یەکن، هەروەها قورسایی هەر شوێنێک، بۆ ئەوەی لاپەڕەیەک کە وشەکەی لە ناونیشاندایە پلەی بەرزتر وەربگرێت. Google دەڵێت وەک «پێڕستی کۆتایی کتێب» کار دەکات، سەدان ملیار لاپەڕە لەخۆ دەگرێت و زۆر زیاترە لە 100 ملیۆن گیگابایت.
A list that goes from each word to the pages that contain it (and where in each page), like the index at the back of a book. It is 'inverted' because a page lists its words, but the index lists, for each word, its pages.
لیستێکە کە لە هەر وشەیەکەوە دەچێت بۆ ئەو وشەکەیان تێدایە (و شوێنی وشەکە لە هەر لاپەڕەیەکدا)، وەک پێڕستی کۆتایی کتێب. پێی دەوترێت «پێچەوانە» چونکە لاپەڕە وشەکانی خۆی ڕیز دەکات، بەڵام ئەم پێڕستە بۆ هەر وشەیەک لاپەڕەکانی ڕیز دەکات.
Crawl, index, serve: step by stepخشاندن، پێڕستکردن، پێشکەشکردن: هەنگاو بە هەنگاو
Guiding the crawler: robots.txt and sitemapsڕێنمایی خشۆکی وێب: robots.txt و نەخشەی تۆڕگە
A site owner can talk to crawlers with two small files at the top of the site:
خاوەنی دەتوانێت بە دوو فایلی بچووک لە سەرەوەی قسە لەگەڵ بکات:
- robots.txt (always at
/robots.txt) lists the parts of the site that crawlers should not visit, for example an admin area or endless search pages. It manages crawler traffic so the server is not overloaded. - A sitemap (often
/sitemap.xml) lists the pages that should be found, with the date each one last changed, so new pages are discovered quickly even if few links point to them.
- robots.txt (هەمیشە لە
/robots.txt) ئەو بەشانەی ڕیز دەکات کە نابێت سەردانیان بکەن، بۆ نموونە بەشی بەڕێوەبردن یان لاپەڕە بێکۆتاکانی گەڕان. هاتوچۆی ڕێک دەخات بۆ ئەوەی بار نەکەوێت. - (زۆرجار
/sitemap.xml) ئەو لاپەڕانە ڕیز دەکات کە دەبێت بدۆزرێنەوە، لەگەڵ بەرواری دوایین گۆڕانکاریی هەر یەکەیان، بۆ ئەوەی لاپەڕە نوێکان بە خێرایی بدۆزرێنەوە تەنانەت ئەگەر کەم ئاماژەیان پێ بکات.
# https://www.chiya-university.example/robots.txt
User-agent: *
Disallow: /admin/
Disallow: /search

Sitemap: https://www.chiya-university.example/sitemap.xml
Explain the codeڕوونکردنەوەی کۆدەکە
- Lineدێڕی 2
The rules below are for every crawler (
*). A lineUser-agent: Googlebotwould address only Google's crawler.یاساکانی خوارەوە بۆ هەموو (
*). دێڕیUser-agent: Googlebotتەنها قسە لەگەڵ Google دەکات.- Lineدێڕی 3-4
Please do not crawl the admin area or the internal search results.
تکایە بەشی بەڕێوەبردن و ئەنجامەکانی گەڕانی ناو مەخشێنە.
- Lineدێڕی 6
Where the sitemap is.
لە کوێیە.
Crawl, index, serve: step by stepخشاندن، پێڕستکردن، پێشکەشکردن: هەنگاو بە هەنگاو
How results are ranked — and what money cannot buyئەنجامەکان چۆن ڕیز دەکرێن — و ئەوەی پارە ناتوانێت بیکڕێت
Nobody outside a search company knows the exact recipe, and it changes often. But the main signals are public, and they make sense:
کەس لە دەرەوەی کۆمپانیای گەڕان ڕەچەتەی تەواو نازانێت و زۆرجار دەگۆڕێت. بەڵام نیشانە سەرەکییەکان ئاشکران و مانادارن:
- Meaning of the search: spelling mistakes are corrected and words with the same meaning are matched («cheap» and «low price»).
- Relevance: the words appear on the page, especially in its title and headings, and the page really answers the question.
- Quality and trust: useful, original content; other respected sites link to it (Google's old PageRank idea is one signal among many).
- Usability: the page loads fast, works on a phone and uses HTTPS.
- Context: your language, your location and your device; for news, how fresh the page is.
- مانای گەڕانەکە: هەڵەی ڕێنووس ڕاست دەکرێتەوە و وشەی هاوواتا پێکەوە دەگونجێنرێن («هەرزان» و «نرخی کەم»).
- گونجان: وشەکان لە لاپەڕەکەدا هەن، بەتایبەتی لە ناونیشان و سەردێڕەکانیدا و لاپەڕەکە بەڕاستی وەڵامی پرسیارەکە دەداتەوە.
- کوالیتی و متمانە: ناوەڕۆکی بەسوود و ڕەسەن؛ تۆڕگە ڕێزدارەکانی تر پێی دەدەن (بیرۆکە کۆنەکەی PageRankـی Google یەک نیشانەیە لە نێوان زۆردا).
- ئاسانیی بەکارهێنان: لاپەڕەکە خێرا دەکرێتەوە، لەسەر مۆبایل کار دەکات و بەکار دەهێنێت.
- دەوروبەر: زمانەکەت، شوێنەکەت و ئامێرەکەت؛ بۆ هەواڵ، ئەوەی لاپەڕەکە چەندە نوێیە.
A search result that appears because the judged the page useful for your search, not because somebody paid. Paid results are adverts and are labelled «Sponsored» or «Ad».
ئەنجامێکی گەڕانە کە دەردەکەوێت چونکە بڕیاری داوە لاپەڕەکە بۆ گەڕانەکەت بەسوودە، نەک لەبەر ئەوەی کەسێک پارەی داوە. ئەنجامە پارەدراوەکان ڕیکلامن و نیشانەی «Sponsored» یان «Ad»یان لەسەرە.
The crawl loop: how a crawler never stopsخولی خشاندن: خشۆکی وێب چۆن هەرگیز ناوەستێت
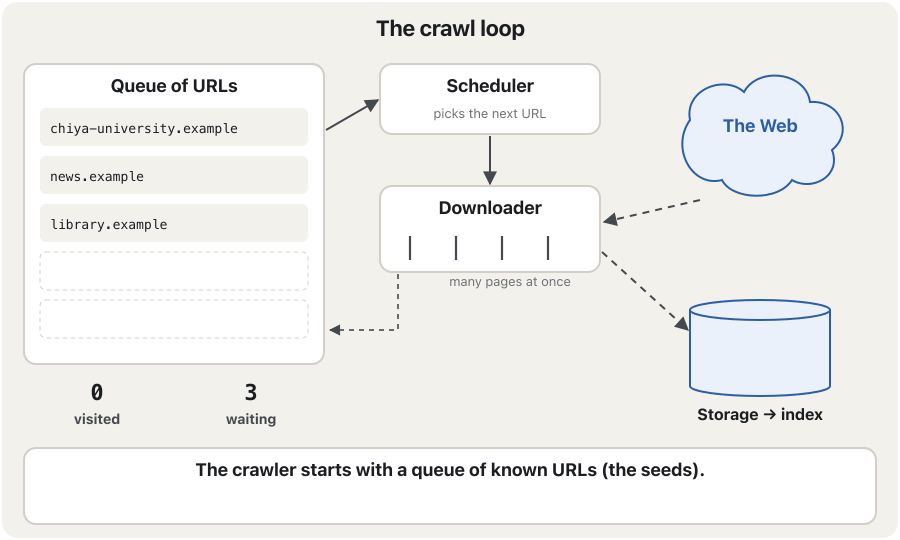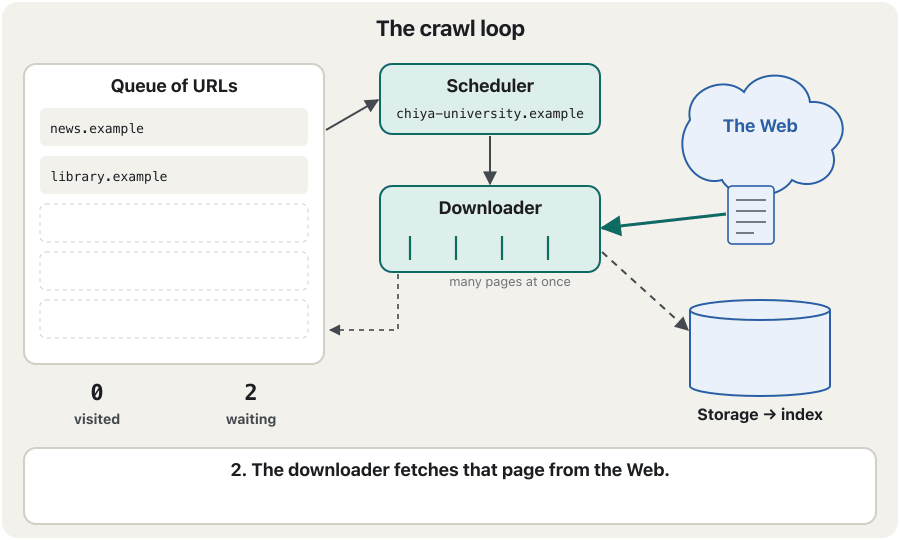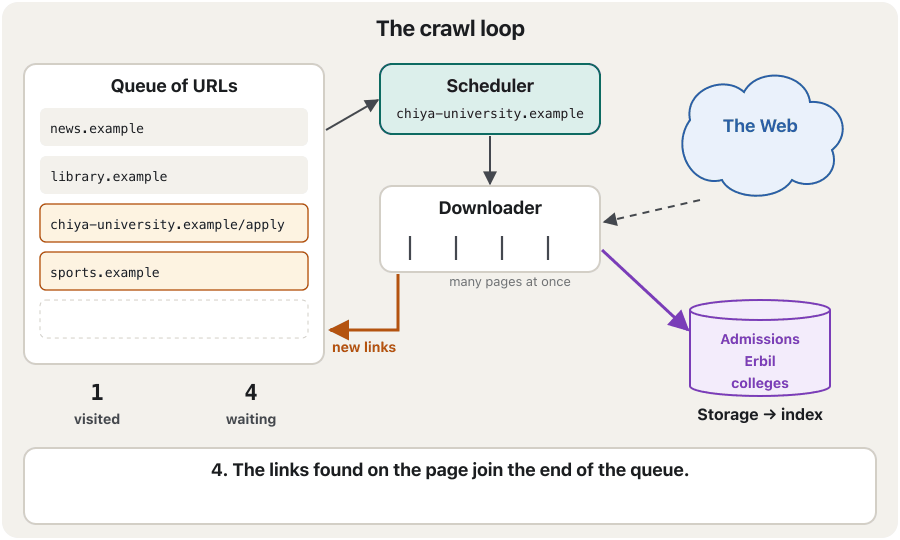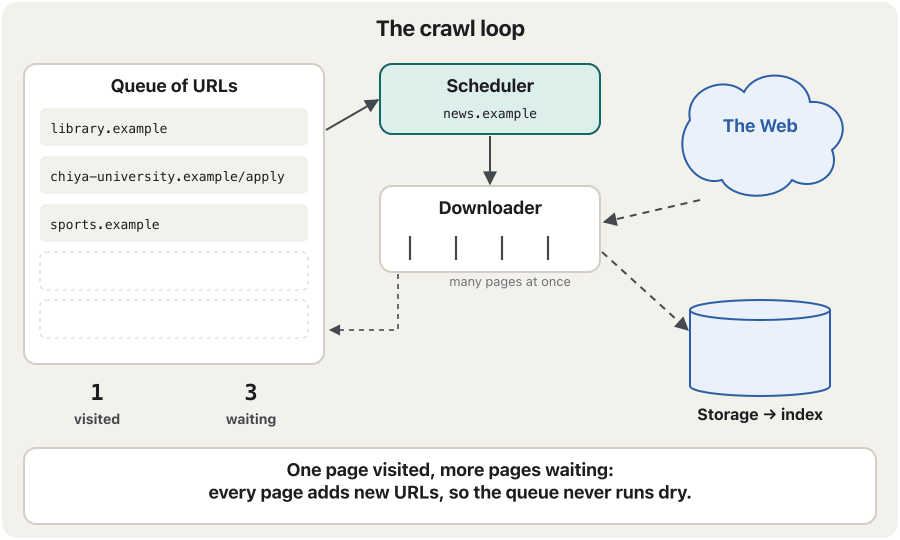
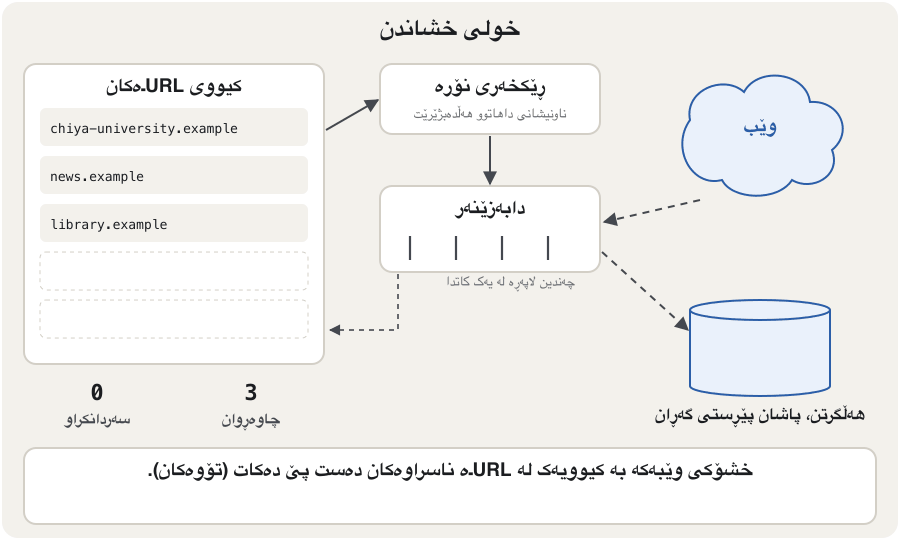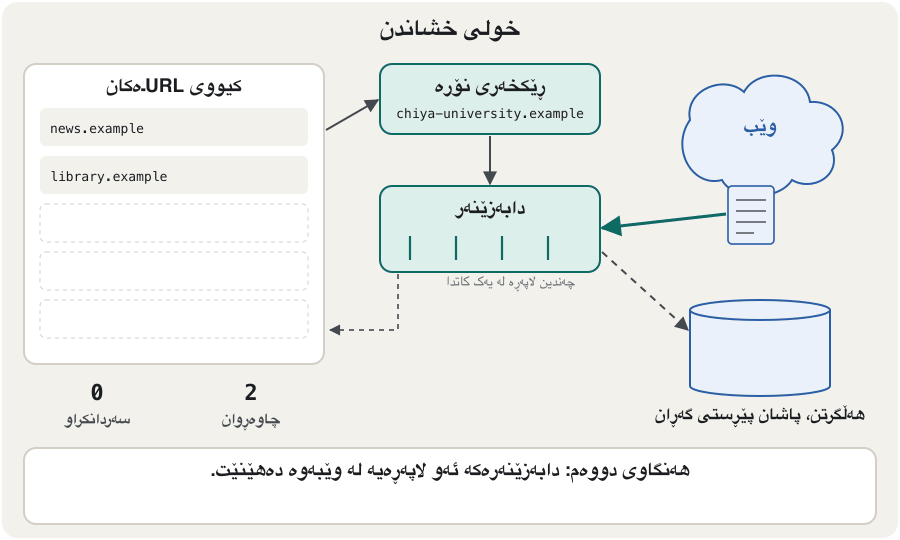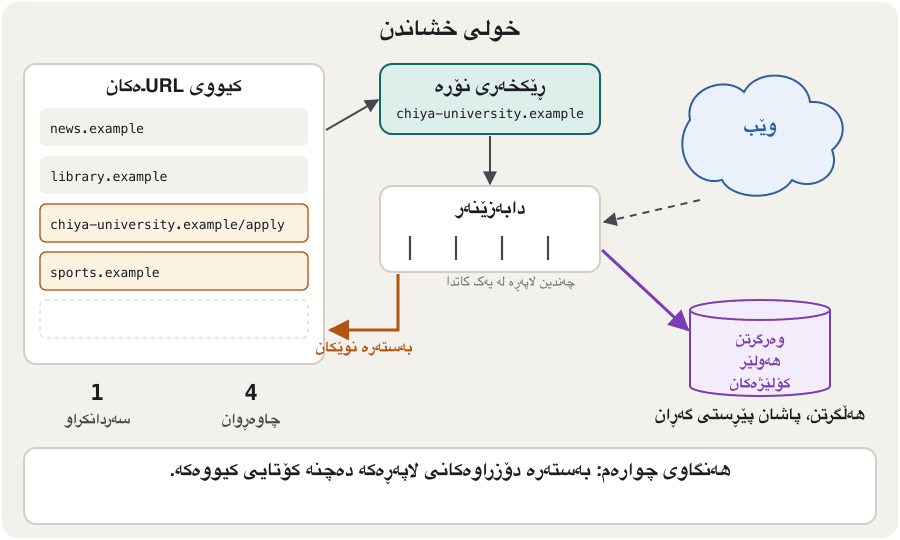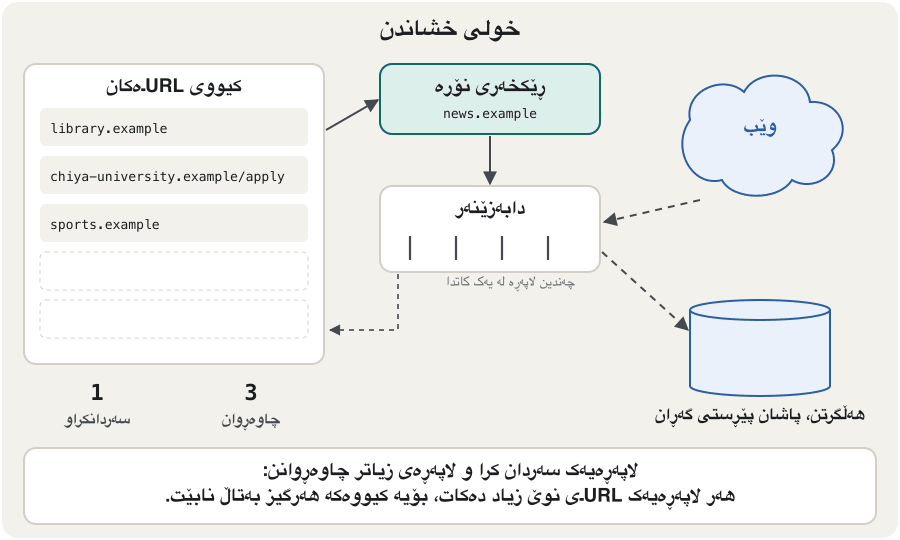
Inside the crawler, a few parts pass URLs round and round. The crawler starts with a list of known addresses, the seeds, and keeps every address still to visit in a queue of URLs (also called the crawl frontier):
لە ناو ، چەند بەشێک بە دەوری یەکدا دەسووڕێنن. بە لیستێک لە ناونیشانە ناسراوەکان دەست پێ دەکات، تۆوەکان (seeds) و هەموو ناونیشانێک کە هێشتا سەردانی نەکراوە لە هەڵدەگرێت (پێی دەوترێت crawl frontierـیش):
- Schedulerڕێکخەری نۆرە (scheduler)
Picks the next URL from the queue. It keeps the crawler polite (not too many requests to one site at once) and decides when known pages are visited again.
داهاتوو لە هەڵدەبژێرێت. ڕێزدار ڕادەگرێت (داواکاریی زۆر لە یەک کاتدا بۆ یەک تۆڕگە نانێرێت) و بڕیار دەدات لاپەڕە ناسراوەکان کەی دووبارە سەردان بکرێنەوە.
- Multi-threaded downloaderدابەزێنەری فرەدەزوو
Downloads many pages from the Web at the same time — thousands of downloads run side by side, because waiting for one slow server at a time would take forever.
لە یەک کاتدا چەندین لاپەڕە لە دادەبەزێنێت — هەزارەها شان بە شانی یەک کار دەکەن، چونکە ئەگەر یەک بە یەک چاوەڕوانی بکات، کارەکە هەرگیز تەواو نابێت.
- Storageشوێنی هەڵگرتن
The text and the metadata of each page (its URL, title, language, date) go to storage, where the indexer turns them into the index.
دەق و میتاداتای هەر لاپەڕەیەک (، ناونیشان، زمان و بەروار) دەچنە شوێنی هەڵگرتن، کە لەوێ پێڕستکەرەکە دەیانکات بە .
- New URLs back into the queueURLـە نوێکان دەگەڕێنەوە ناو کیوو
Every link found on the page that the crawler has not seen before is added to the queue. Each page adds new addresses, so the loop never ends.
هەر کە لە لاپەڕەکەدا دۆزرایەوە و پێشتر نەیبینیوە، دەخرێتە ناو . هەر لاپەڕەیەک ناونیشانی نوێ زیاد دەکات، بۆیە خولەکە هەرگیز کۆتایی نایەت.
Kinds of search engineجۆرەکانی بزوێنەری گەڕان
Search engines differ in what you can search for. The slide's list, brought up to date:
لەوەدا جیاوازن کە چی دەتوانیت بگەڕێیت. لیستەکەی سلایدەکە، نوێکراوە:
| Kindجۆر | What you searchچی دەگەڕێیت | Examples in 2026نموونەکان لە 2026 |
|---|---|---|
| Text search, generalگەڕانی دەق، گشتی | Web pages on any subject لەسەر هەر بابەتێک | Google, Bing, Baidu, Yandex, DuckDuckGoGoogle، Bing، Baidu، Yandex، DuckDuckGo |
| Text search, specialisedگەڕانی دەق، تایبەت | Only one field, such as research papersتەنها یەک بوار، وەک توێژینەوە زانستییەکان | Google Scholar (all sciences), CiteSeerX (computer science), PubMed (medicine)Google Scholar (هەموو زانستەکان)، CiteSeerX (زانستی )، PubMed (پزیشکی) |
| Image searchگەڕانی وێنە | Pictures, found by their words and also by their content — colours, shapes, faces, objectsوێنە، کە بە وشەکانیان و هەروەها بە ناوەڕۆکیان دەدۆزرێنەوە — ڕەنگ، شێوە، ڕوخسار، شت | Google Images, Bing ImagesGoogle Images، Bing Images |
| Reverse-image searchگەڕانی پێچەوانە بە وێنە | You give a picture; it finds where it appears and what is in itوێنەیەک دەدەیت؛ دەدۆزێتەوە لە کوێ دەرکەوتووە و چی تێدایە | Google Lens, Bing Visual SearchGoogle Lens، Bing Visual Search |
| Video searchگەڕانی ڤیدیۆ | Image search with a time dimension: frames, speech and captions inside the videoگەڕانی وێنە لەگەڵ ڕەهەندی کات: وێنەکان، قسە و ژێرنووسی ناو ڤیدیۆکە | YouTube search, the Videos tab of Google or Bingگەڕانی YouTube، تابی Videos لە Google یان Bing |
Kinds of search engineجۆرەکانی بزوێنەری گەڕان
Who builds the index: crawlers, people or bothکێ پێڕستی گەڕان دروست دەکات: خشۆکەکانی وێب، مرۆڤ یان هەردووکیان
Search engines also differ in how their index is made:
هەروەها لەوەدا جیاوازن کە چۆن دروست دەکرێت:
| Kind of indexجۆری | How it is madeچۆن دروست دەکرێت | Examplesنموونەکان |
|---|---|---|
| Crawler-poweredبە | Programs crawl and index automatically. Today's normal search engine. بە شێوەی خۆکار دەخشێنن و پێڕست دروست دەکەن. ئاسایی ئەمڕۆ. | google.com, bing.comgoogle.com، bing.com |
| Human-powered (a web directory)بە دەستی مرۆڤ () | Editors read sites and sort them into categories by hand, like a telephone book.دەستکاران تۆڕگەکان دەخوێننەوە و بە دەست لە پۆلەکاندا ڕیزیان دەکەن، وەک دەفتەری تەلەفۆن. | Yahoo! Directory (1994–2014), DMOZ (1998–2017) — both closedYahoo! Directory (1994–2014)، DMOZ (1998–2017) — هەردووکیان داخراون |
| Hybridتێکەڵ | A crawler plus addresses that site owners submit themselves (and sometimes human checks). لەگەڵ ئەو ناونیشانانەی خاوەنی تۆڕگەکان خۆیان دەینێرن (و هەندێک جار پشکنینی مرۆڤ). | Submitting a sitemap in Google Search Console or Bing Webmaster Toolsناردنی لە Google Search Console یان Bing Webmaster Tools |
| Semanticواتایی | The index stores meanings and real things (people, places, dates) and the links between them, not only words. واتا و شتە ڕاستەقینەکان (کەس، شوێن، بەروار) و پەیوەندیی نێوانیان هەڵدەگرێت، نەک تەنها وشە. | Google's Knowledge Graph, which fills the information box beside the resultsKnowledge Graphـی Google، کە سندووقی زانیاریی تەنیشت ئەنجامەکان پڕ دەکاتەوە |
A list of sorted into categories by people, like a telephone book of the Web. Yahoo! Directory and DMOZ were famous examples; both closed when keyword took over.
لیستێکی کە مرۆڤ بە دەست لە پۆلەکاندا ڕیزی کردوون، وەک دەفتەری تەلەفۆنی . Yahoo! Directory و DMOZ نموونەی ناسراو بوون؛ هەردووکیان داخران کاتێک بە وشەی گەڕان جێیان گرتنەوە.
Search engines as one kind of website, next to social, business and learning sites, are compared in Website types.
وەک جۆرێک لە ، لە تەنیشت تۆڕگەکانی کۆمەڵایەتی، بازرگانی و فێربوون، لە جۆرەکانی تۆڕگەدا بەراورد کراون.
Searching by the meaning of the question and the things it talks about, not only by matching the same words. A semantic search engine knows that «capital of Kurdistan Region» and «Erbil» are about the same thing.
گەڕان بەپێی واتای پرسیارەکە و ئەو شتانەی باسیان دەکات، نەک تەنها بە دۆزینەوەی هەمان وشەکان. بە دەزانێت «پایتەختی هەرێمی کوردستان» و «هەولێر» دەربارەی هەمان شتن.
Reading a results pageخوێندنەوەی لاپەڕەی ئەنجامەکان
Search for a university's name and the results page shows much more than a list of links. Here is an original drawing of such a page for an invented university, «Chiya University». Every part comes from a different place in the search engine:
بە ناوی زانکۆیەک بگەڕێ و لاپەڕەی ئەنجامەکان زۆر زیاتر لە لیستێکی پیشان دەدات. ئەمە وێنەیەکی ڕەسەنی لاپەڕەیەکی وایە بۆ زانکۆیەکی داهێنراو، «زانکۆی چیا». هەر بەشێکی لە شوێنێکی جیاوازی دێت:
| Partبەش | Where it comes fromلە کوێوە دێت |
|---|---|
| 1 Sponsored result1 ئەنجامی Sponsored | An advert someone paid for. It can look almost like a normal result: read the label.ڕیکلامێکە کەسێک پارەی بۆ داوە. دەکرێت زۆر لە ئەنجامی ئاسایی بچێت: نیشانەکە بخوێنەوە. |
| 2 Organic result with site links2 بە تۆڕگە | Chosen from the index by ranking. For an official site the engine adds links to its main sections.بە ڕیزبەندی لە هەڵبژێردراوە. بۆ تۆڕگەیەکی فەرمی بۆ بەشە سەرەکییەکانی زیاد دەکات. |
| 3 More organic results3 | Other pages about the same name, ranked lower.لاپەڕەی تر دەربارەی هەمان ناو، بە پلەی نزمتر. |
| 4 People also ask4 سندووقی People also ask | Questions other people searched, with short answers taken from pages.ئەو پرسیارانەی خەڵکی تر گەڕاون، بە وەڵامی کورت کە لە لاپەڕەکانەوە وەرگیراون. |
| 5 Knowledge panel5 سندووقی زانیاری (knowledge panel) | Facts from the engine's semantic database (Google's Knowledge Graph): map, address, phone, founding year — for companies often the founders.زانیاری لە واتاییەکەی (Knowledge Graphـی Google): نەخشە، ناونیشان، تەلەفۆن، ساڵی دامەزراندن — بۆ کۆمپانیاکان زۆرجار دامەزرێنەرەکانیش. |
Getting found: SEOدۆزرانەوە: SEO
The crawling idea has a practical use for everyone who builds a website. Search engine optimisation (SEO) is the work of making a site or page more visible in a search engine's unpaid results — also called «natural», «organic» or «earned» results. You cannot buy these places, so you earn them by making pages that crawlers can read and people find useful.
بیرۆکەی خشاندن سوودێکی کرداریی بۆ هەموو ئەو کەسانە هەیە کە دروست دەکەن. () ئەو کارەیە کە یان لاپەڕەیەک لە ئەنجامە بێپارەکانی زیاتر دیار دەکات — ئەو ئەنجامانەی بە «سروشتی»، «ئۆرگانیک» یان «بەدەستهێنراو» ناو دەبرێن. ناتوانیت ئەم شوێنانە بکڕیت، بۆیە بە دروستکردنی لاپەڕەی وا بەدەستیان دەهێنیت کە بتوانن بیانخوێننەوە و خەڵک بە بەسوودیان بزانن.
Improving a so that can find and understand it and show it higher in their unpaid () results — for example clear titles, headings, and fast pages that work on phones.
باشترکردنی بە شێوەیەک کە بیدۆزنەوە، تێی بگەن و لە ئەنجامە بێپارەکانیاندا () بەرزتر پیشانی بدەن — بۆ نموونە ناونیشانی ڕوون، سەردێڕ، و لاپەڕەی خێرا کە لەسەر مۆبایل کار بکات.
- A clear, unique title for every page, and a short description — they become the blue link and the text under it.
- Headings and helpful, original text that use the words people really search for.
- Alt text on pictures and descriptive link text («exam timetable», not «click here»).
- Readable addresses: /admissions, not /page?id=8341.
- Fast pages that work on phones, served over HTTPS.
- A sitemap, and a 301 redirect when a page moves, so links and rank follow it to the new address (HTML and 301 redirects).
- ناونیشانێکی ڕوون و تایبەت بۆ هەر لاپەڕەیەک و وەسفێکی کورت — دەبنە شینەکە و ئەو دەقەی لە ژێریدایە.
- سەردێڕ و دەقی بەسوود و ڕەسەن کە ئەو وشانە بەکار دەهێنن خەڵک بەڕاستی بەدوایاندا دەگەڕێن.
- لەسەر وێنەکان و دەقی وەسفکەری («خشتەی تاقیکردنەوەکان»، نەک «لێرە کلیک بکە»).
- ڕوون: /admissions، نەک /page?id=8341.
- لاپەڕەی خێرا کە لەسەر مۆبایل کار بکەن، بە .
- و 301 کاتێک لاپەڕەیەک دەگوازرێتەوە، بۆ ئەوەی و پلەکەی بەدوایدا بچن بۆ نوێیەکە (ئاڕاستەکردنەوەی HTML و 301).
<title>Admissions 2026 – Chiya University</title>
<meta name="description" content="How to apply, deadlines and fees for 2026.">
<img src="library.jpg" alt="Students reading in the university library">
Explain the codeڕوونکردنەوەی کۆدەکە
- Lineدێڕی 1
The title: shown on the browser tab and as the blue link in results.
ناونیشان: لەسەر تابی و وەک شینەکە لە ئەنجامەکاندا پیشان دەدرێت.
- Lineدێڕی 2
A short description the engine may show under the link.
وەسفێکی کورت کە لەوانەیە لە ژێر پیشانی بدات.
- Lineدێڕی 3
Alt text tells crawlers (and blind users) what the picture shows.
بە (و ) دەڵێت وێنەکە چی پیشان دەدات.
Where these tags live in a page is shown in the structure of an HTML document.
شوێنی ئەم تاگانە لە لاپەڕەدا لە پێکهاتەی بەڵگەنامەیەکی HTMLدا پیشان دراوە.
What SEO is and its two main kinds: on-page work (keywords, content, page speed) and off-page work (good backlinks).
چییە و دوو جۆرە سەرەکییەکەی: کار لەسەر خودی لاپەڕەکە (، ناوەڕۆک، خێرایی لاپەڕە) و کار لە دەرەوەی لاپەڕەکە ( باش لە ترەوە).
Whole video (5:04): what SEO is, on-page and off-page SEO, and a short quiz.
هەموو ڤیدیۆکە (5:04): چییە، ناو لاپەڕە و دەرەوەی لاپەڕە، لەگەڵ چەند پرسیارێکی کورت بۆ تاقیکردنەوە.
Getting found: SEOدۆزرانەوە: SEO
What SEO gives a website and a businessSEO چی دەدات بە تۆڕگەیەک و بازرگانییەک
Think of a small bookshop in Duhok with a website. Good SEO helps in two places:
کتێبفرۆشییەکی بچووک لە دهۆک بهێنە بەرچاو کە هەیە. باش لە دوو شوێندا یارمەتی دەدات:
| For the websiteبۆ | For the businessبۆ بازرگانییەکە |
|---|---|
| Market analysis: learn what people near you search for («Kurdish novels», «school books Duhok»).شیکاری بازاڕ: بزانە خەڵکی نزیکت بەدوای چیدا دەگەڕێن («ڕۆمانی کوردی»، «کتێبی قوتابخانە دهۆک»). | Better-quality traffic: visitors arrive already looking for what you sell.سەردانکەری باشتر: سەردانکەران دێن و پێشتر بەدوای ئەوەدا دەگەڕێن کە تۆ دەیفرۆشیت. |
| Keyword research: choose the words to use in titles and headings.لێکۆڵینەوەی : ئەو وشانە هەڵبژێرە کە لە ناونیشان و سەردێڕەکاندا بەکاریان دەهێنیت. | More sales: more of those visitors buy.فرۆشی زیاتر: زیاتر لەو سەردانکەرانە دەکڕن. |
| An SEO-friendly site: fast, clear, readable on phones.تۆڕگەیەکی گونجاو بۆ : خێرا، ڕوون و لەسەر مۆبایل بە ئاسانی دەخوێندرێتەوە. | A bigger client base: people who never passed the shop find it.بنکەیەکی گەورەتری کڕیار: ئەو کەسانەی هەرگیز بەلای دوکانەکەدا تێنەپەڕیون دەیدۆزنەوە. |
| Higher ranking in organic results.پلەی بەرزتر لە . | Better return on investment: organic clicks are free, adverts are paid per click.قازانجی باشتر لە پارەی خەرجکراو: کلیکی سروشتی بێپارەیە، ڕیکلام بۆ هەر کلیکێک پارەی دەوێت. |
| More visitors.سەردانکەری زیاتر. | Beating competitors who appear lower.تێپەڕاندنی ڕکابەران کە لە خوارەوەتر دەردەکەون. |
Search engines then and nowبزوێنەرەکانی گەڕان ئەوسا و ئێستا
The course slide shows the logos of ten famous names. Most of them are gone, bought or renamed — a reminder of how fast this market changes:
سلایدەکەی کۆرسەکە لۆگۆی دە ناوی بەناوبانگ پیشان دەدات. زۆربەیان نەماون، کڕدراون یان ناویان گۆڕاوە — بیرخستنەوەیەک کە ئەم بازاڕە چەندە خێرا دەگۆڕێت:
| Name on the slideناو لەسەر سلایدەکە | What happenedچی ڕوویدا |
|---|---|
| Still the most used search engine in the world.هێشتا بەکارهێنراوترین جیهانە. | |
| Yahoo! | Still a portal, but since a 2009 deal with Microsoft most of its search results come from Bing.هێشتا دەروازەیەکە، بەڵام لە ڕێککەوتنێکی 2009 لەگەڵ Microsoftـەوە زۆربەی ئەنجامەکانی گەڕانی لە Bingـەوە دێن. |
| MSN Search | Became Live Search, then Bing (2009).بوو بە Live Search، پاشان Bing (2009). |
| AltaVista | Bought by Yahoo! in 2003 and closed on 8 July 2013.لە 2003 Yahoo! کڕی و لە 8ـی تەممووزی 2013 داخرا. |
| Ask Jeeves | Renamed Ask.com in 2006; closed on 1 May 2026.لە 2006 ناوی بوو بە Ask.com؛ لە 1ـی ئایاری 2026 داخرا. |
| Inktomi | A search technology company bought by Yahoo! in 2003.کۆمپانیایەکی تەکنەلۆجیای گەڕان کە Yahoo! لە 2003 کڕی. |
| Overture | Sold the paid listings (adverts) in results; bought by Yahoo! in 2003.ڕیکلامی ناو ئەنجامەکانی دەفرۆشت؛ Yahoo! لە 2003 کڕی. |
| AOL Search | Shows Bing's results since 2016.لە 2016ـەوە ئەنجامەکانی Bing پیشان دەدات. |
| Netscape | The browser ended in 2008; its search went with it. لە 2008 کۆتایی هات؛ گەڕانەکەشی لەگەڵیدا ڕۆیشت. |
| Excite | A web portal that showed other engines' results; the US site closed in August 2026.دەروازەیەکی وێب بوو کە ئەنجامی تری پیشان دەدا؛ تۆڕگە ئەمریکییەکەی لە ئابی 2026 داخرا. |
Search engines then and nowبزوێنەرەکانی گەڕان ئەوسا و ئێستا
From directories to AI answersلە ڕێبەرەکانی وێبەوە بۆ وەڵامی ژیریی دەستکرد
The way people search changed with the Web itself. In Web 1.0 people browsed directories — category by category, like a library shelf. Web 2.0 brought searching by keywords and tags (labels that users add, such as hashtags). Today's search looks at context and relevance: the meaning of the question, where you are and what you probably want. The whole comparison of Web 1.0, 2.0 and 3.0 is in The Internet and the World Wide Web.
شێوەی گەڕانی خەڵک لەگەڵ خودی گۆڕا. لە Web 1.0دا خەڵک بە دەگەڕان — پۆل بە پۆل، وەک ڕەفی کتێبخانە. Web 2.0 گەڕانی بە و نیشانە هێنایە ئاراوە (ئەو نیشانانەی زیادیان دەکەن، وەک هاشتاگ). گەڕانی ئەمڕۆ سەیری دەوروبەر و گونجان دەکات: مانای پرسیارەکە، تۆ لە کوێیت و بە ئەگەری زۆر چیت دەوێت. بەراوردی تەواوی Web 1.0، 2.0 و 3.0 لە ئینتەرنێت و وێبدایە.
In 2026 the big general engines are Google and Bing, with Baidu in China, Yandex in Russia and Naver in Korea; DuckDuckGo and Brave Search sell themselves on privacy. AI chatbots that search the Web and summarise what they find are the newest way to search — but they still need an index built by crawlers.
لە 2026دا Google و Bing گەورەترین ، لەگەڵ Baidu لە چین، Yandex لە ڕووسیا و Naver لە کۆریا؛ DuckDuckGo و Brave Search خۆیان بە پاراستنی دەناسێنن. کە لە دەگەڕێن و ئەوەی دەیدۆزنەوە پوختە دەکەن نوێترین ڕێگەی گەڕانن — بەڵام هێشتا پێویستیان بە هەیە کە دروستیان کردووە.
Common mistakesهەڵە باوەکان
| Mistakeهەڵە | What is trueئەوەی ڕاستە |
|---|---|
| «The search engine reads the whole Web when I press Enter.»« کاتێک Enter دادەگرم هەموو دەخوێنێتەوە.» | It answers from its index, built earlier by crawlers. New pages appear only after they are crawled and indexed.لە وەڵام دەداتەوە کە پێشتر دروستیان کردووە. لاپەڕە نوێکان تەنها دوای خشاندن و پێڕستکردن دەردەکەون. |
| «The first result is the truth.»«یەکەم ئەنجام ڕاستییەکەیە.» | Ranking measures relevance and popularity, not truth. Check who wrote the page and compare sources.ڕیزبەندی گونجان و ناوبانگ دەپێوێت، نەک ڕاستی. بپشکنە کێ لاپەڕەکەی نووسیوە و سەرچاوەکان بەراورد بکە. |
| Clicking the top link without seeing «Sponsored».کلیککردن لە یەکەم بێ بینینی «Sponsored». | The top places are often adverts; fake sites sometimes buy them. Read the label and the address.شوێنەکانی سەرەوە زۆرجار ڕیکلامن؛ تۆڕگە ساختەکان هەندێک جار دەیانکڕن. نیشانەکە و ناونیشانەکە بخوێنەوە. |
| Using robots.txt to hide private pages.بەکارهێنانی robots.txt بۆ شاردنەوەی لاپەڕە تایبەتەکان. | It is a public, polite request. Use a password, or noindex to stay out of results.داواکارییەکی گشتی و ڕێزدارانەیە. بەکار بهێنە، یان noindex بۆ ئەوەی لە ئەنجامەکاندا نەبیت. |
| Paying for «guaranteed first place».پارەدان بۆ «پلەی یەکەمی دڵنیاکراو». | No one can buy organic rank. Earn it with useful pages; pay only for clearly labelled adverts.کەس ناتوانێت پلەی سروشتی بکڕێت. بە لاپەڕەی بەسوود بەدەستی بهێنە؛ تەنها بۆ ڕیکلامی بە ڕوونی نیشانەکراو پارە بدە. |
| Stuffing a page with keywords.پڕکردنی لاپەڕە بە . | Write for people. Repeated or hidden keywords count as spam.بۆ خەڵک بنووسە. وشەی دووبارەکراو یان شاراوە بە دادەنرێت. |
| Thinking a crawler «worm» is malware.بیرکردنەوە لەوەی «worm»ـی . | It is an old nickname for a crawler; a malware worm is a different thing.ناوێکی کۆنی ؛ شتێکی ترە. |
Exercisesڕاهێنانەکان
Define a search engine. Then name its three parts and say in one sentence what each part does.
پێناسە بکە. پاشان سێ بەشەکەی ناو ببە و بە یەک ڕستە بڵێ هەر بەشێک چی دەکات.
Show answerوەڵامەکە پیشان بدە
A search engine is a searchable database of information collected from web pages: it indexes the information, stores it in a huge database and gives users an interface to search it. (1) The spider/crawler finds and downloads pages by following links and adds them to the database (e.g. Googlebot). (2) The index is the database holding a copy of each page, organised as a word list. (3) The search software takes the user's search term, looks it up in the index and returns the results in ranked order.
گەڕانپێکراوە لە زانیارییەکانی : زانیارییەکان پێڕست دەکات، لە گەورەدا هەڵیان دەگرێت و ڕووکارێک بە دەدات بۆ گەڕان تێیدا. (1) بە بەدواداچوونی لاپەڕەکان دەدۆزێتەوە و دایان دەبەزێنێت و دەیانخاتە ناو (بۆ نموونە Googlebot). (2) کە کۆپییەکی هەر لاپەڕەیەکی تێدایە، وەک لیستێکی وشە ڕێکخراوە. (3) گەڕان وەردەگرێت، لە بەدوایدا دەگەڕێت و ئەنجامەکان بە ڕیزبەندی دەگەڕێنێتەوە.
Three pages: (1) «cheap laptop Erbil», (2) «laptop repair Sulaymaniyah», (3) «cheap phone repair Erbil». Write the inverted index (word → pages). Then answer the searches «cheap Erbil» and «laptop repair».
سێ لاپەڕە: (1) «لاپتۆپی هەرزان هەولێر»، (2) «چاککردنەوەی لاپتۆپ سلێمانی»، (3) «چاککردنەوەی مۆبایلی هەرزان هەولێر». بنووسە (وشە ← لاپەڕەکان). پاشان وەڵامی گەڕانەکانی «هەرزان هەولێر» و «لاپتۆپ چاککردنەوە» بدەرەوە.
Hintئاماژە
A page is a result only if it is in the row of every word you searched.
لاپەڕەیەک تەنها ئەو کاتە ئەنجامە کە لە ڕیزی هەموو ئەو وشانەدا بێت کە گەڕاویت.
Show answerوەڵامەکە پیشان بدە
| Wordوشە | Pagesلاپەڕەکان |
|---|---|
| cheapهەرزان | 1, 3 |
| laptopلاپتۆپ | 1, 2 |
| Erbilهەولێر | 1, 3 |
| repairچاککردنەوە | 2, 3 |
| Sulaymaniyahسلێمانی | 2 |
| phoneمۆبایل | 3 |
«cheap Erbil»: cheap → 1, 3 and Erbil → 1, 3, so pages 1 and 3. «laptop repair»: laptop → 1, 2 and repair → 2, 3, so page 2 only.
«هەرزان هەولێر»: هەرزان ← 1، 3 و هەولێر ← 1، 3، بۆیە لاپەڕەکانی 1 و 3. «لاپتۆپ چاککردنەوە»: لاپتۆپ ← 1، 2 و چاککردنەوە ← 2، 3، بۆیە تەنها لاپەڕەی 2.
A school site has a /teachers/ area that needs a login and a /calendar/ that creates endless pages. Write a robots.txt that keeps all crawlers out of both and gives the sitemap at https://school.example/sitemap.xml. Then say what still protects /teachers/.
تۆڕگەی قوتابخانەیەک بەشێکی /teachers/ـی هەیە کە پێویستی بە هەیە و /calendar/ کە لاپەڕەی بێکۆتا دروست دەکات. robots.txt بنووسە کە هەموو لە هەردووکیان دوور بخاتەوە و لە https://school.example/sitemap.xml بدات. پاشان بڵێ چی هێشتا /teachers/ دەپارێزێت.
Show answerوەڵامەکە پیشان بدە
User-agent: *
Disallow: /teachers/
Disallow: /calendar/

Sitemap: https://school.example/sitemap.xml
The login protects /teachers/. robots.txt only asks polite crawlers not to visit; it does not stop a person or a bad bot.
/teachers/ دەپارێزێت. robots.txt تەنها داواکارییەکی ڕێزدارانەیە بۆ ؛ مرۆڤ یان بۆتێکی خراپ ڕاناگرێت.
A bakery in Sulaymaniyah has a home page titled «Home», its address /index.php?p=1, a photo with no alt text and the words «click here» as its only link to the menu. Suggest four changes.
ناونیشانی نانەواخانەیەک لە سلێمانی «Home»ـە، /index.php?p=1ـە، وێنەیەکی بێ تێدایە و وشەی «لێرە کلیک بکە» تاکە بۆ لیستی خواردنەکان. چوار گۆڕانکاری پێشنیار بکە.
Show answerوەڵامەکە پیشان بدە
- Title: «Fresh bread and kleicha – Shilan Bakery, Sulaymaniyah».
- A readable address such as /menu.
- Alt text: «Fresh samoon bread on the counter».
- Link text «See our menu and prices» instead of «click here»; and check that the page loads fast on a phone.
- ناونیشان: «نانی تازە و کلێچە – نانەواخانەی شیلان، سلێمانی».
- ڕوون وەک /menu.
- : «نانی سەموونی تازە لەسەر مێزەکە».
- دەقی «لیستی خواردن و نرخەکانمان ببینە» لە جیاتی «لێرە کلیک بکە»؛ و بپشکنە کە لاپەڕەکە لەسەر مۆبایل خێرا دەکرێتەوە.
Which kind of search engine or index fits each task? (a) Find research papers on solar panels. (b) Find where a photo of you has been posted. (c) A 1999 list of Kurdish websites sorted by editors into categories. (d) «How far is Halabja from Sulaymaniyah?» answered with a number.
کام جۆری یان بۆ هەر ئەرکێک دەگونجێت؟ (أ) دۆزینەوەی توێژینەوەی زانستی دەربارەی پانێڵی خۆر. (ب) دۆزینەوەی ئەوەی وێنەیەکی تۆ لە کوێ بڵاو کراوەتەوە. (ج) لیستێکی ساڵی 1999ـی کوردی کە دەستکاران لە پۆلەکاندا ڕیزیان کردبوو. (د) «هەڵەبجە چەندە لە سلێمانییەوە دوورە؟» کە بە ژمارەیەک وەڵام دەدرێتەوە.
Show answerوەڵامەکە پیشان بدە
- (a) A specialised text engine such as Google Scholar.
- (b) Reverse-image search, for example Google Lens.
- (c) A human-powered web directory.
- (d) Semantic search: the engine understands the two places and the question.
- (أ) دەقی تایبەت وەک Google Scholar.
- (ب) گەڕانی پێچەوانە بە وێنە، بۆ نموونە Google Lens.
- (ج) بە دەستی مرۆڤ.
- (د) : لە هەردوو شوێنەکە و پرسیارەکە تێدەگات.
Summaryپوختە
- A search engine answers from its index, a huge database built in advance — not from the live Web.
- We need search engines for variety, organisation and precision.
- Three parts: the crawler (spider, bot — Googlebot, Bingbot), the index and the search software that ranks.
- Three stages: crawl (links, sitemaps, robots.txt) → index (word list with places and weights, compressed) → serve (ranked by relevance, quality and context).
- An inverted index maps each word to its pages; a search keeps the pages that contain all the words.
- The crawl loop: scheduler → downloader → storage → new URLs back into the queue.
- Kinds: general and specialised text, image, reverse-image and video search; crawler, human (directory), hybrid and semantic indexes.
- Adverts are labelled Sponsored; organic places cannot be bought — they are earned with SEO.
- لە وەڵام دەداتەوە، گەورە کە پێشتر دروست کراوە — نەک لە زیندووەوە.
- پێویستمان بە هەیە بۆ جۆراوجۆری، ڕێکخستن و وردی.
- سێ بەش: (spider، bot — Googlebot، Bingbot)، و گەڕان کە ڕیز دەکات.
- سێ قۆناغ: خشاندن (، ، robots.txt) ← پێڕستکردن (لیستی وشە لەگەڵ شوێن و قورسایی، پەستێنراو) ← پێشکەشکردن (ڕیزکراو بەپێی گونجان، کوالیتی و دەوروبەر).
- هەر وشەیەک دەبەستێتەوە بە لاپەڕەکانییەوە؛ گەڕان ئەو لاپەڕانە دەهێڵێتەوە کە هەموو وشەکانیان تێدایە.
- خولی خشاندن: ڕێکخەری نۆرە ← دابەزێنەر ← شوێنی هەڵگرتن ← نوێکان دەگەڕێنەوە ناو .
- جۆرەکان: گەڕانی دەقی گشتی و تایبەت، وێنە، پێچەوانە بە وێنە و ڤیدیۆ؛ ، مرۆڤ ()، تێکەڵ و واتایی.
- ڕیکلامەکان نیشانەی Sponsoredیان لەسەرە؛ شوێنە سروشتییەکان ناکڕدرێن — بە بەدەست دێن.
Why can a search engine answer in under a second?بۆچی بزوێنەری گەڕان دەتوانێت لە کەمتر لە چرکەیەکدا وەڵام بداتەوە؟
It looks the words up in an index it built earlier, instead of reading web pages while you wait.
وشەکان لە دەدۆزێتەوە کە پێشتر دروستی کردووە، لە جیاتی خوێندنەوەی لە کاتی چاوەڕوانیی تۆدا.
What does a sitemap do, and what does robots.txt do?نەخشەی تۆڕگە چی دەکات و robots.txt چی دەکات؟
A sitemap lists pages that should be found; robots.txt lists parts crawlers should not visit. Neither is a security measure.
ئەو لاپەڕانە ڕیز دەکات کە دەبێت بدۆزرێنەوە؛ robots.txt ئەو بەشانە ڕیز دەکات کە نابێت سەردانیان بکەن. هیچیان ڕێوشوێنی پاراستن نین.
Name two benefits of SEO for a business.دوو سوودی SEO بۆ بازرگانییەک ناو ببە.
Any two of: better-quality traffic, more sales, a bigger client base, a better return on investment, beating competitors.
هەر دووانێک لەمانە: سەردانکەری باشتر، فرۆشی زیاتر، بنکەی گەورەتری کڕیار، قازانجی باشتر لە پارەی خەرجکراو، تێپەڕاندنی ڕکابەران.
Lesson complete!وانەکە تەواو بوو!
Well done. Review the key terms, then go on to the next lesson.دەستخۆش. سەیرێکی زاراوە سەرەکییەکان بکەرەوە، پاشان بڕۆ بۆ وانەی داهاتوو.
Key termsزاراوە سەرەکییەکان
How E-mail Worksئیمەیڵ چۆن کار دەکات
Related lecturesوانە پەیوەندیدارەکان
- The Internet and the Webئینتەرنێت و وێب
- Browsers, Web Servers and URLsتۆڕگەڕەکان، ڕاژەکارەکانی وێب و URL
- The Internet and the Webئینتەرنێت و وێب
- Redirects: Sending the Browser Somewhere Elseئاڕاستەکردنەوە: ناردنی تۆڕگەڕ بۆ شوێنێکی تر
- HTML Basics: Documents, Links and Tablesبنەماکانی HTML: بەڵگەنامە، بەستەرەکان و خشتەکان
- Search Problems: States, Actions, Goals and Costsکێشەکانی گەڕان: دۆخەکان، کردەوەکان، ئامانج و کۆست
- Agents, Sensors and Actuators; Rational Agentsئەیجێنتەکان، هەستەوەرەکان و جووڵێنەرەکان؛ ئەیجێنتە عەقڵانییەکان
- How E-mail Worksئیمەیڵ چۆن کار دەکات
- Static and Dynamic Websites and Website Typesلاپەڕەتۆڕە نەگۆڕەکان، لاپەڕەتۆڕە داینامیکەکان و جۆرەکانی تۆڕگە
- The Website Development Life Cycleسووڕی ژیانی گەشەپێدانی تۆڕگە
References and further readingسەرچاوەکان و خوێندنەوەی زیاتر
- Google Search Central: In-depth guide to how Google Search works (crawling, indexing, serving; no payment for ranking)
- Google Search Central: Introduction to robots.txt
- Google Search Central: SEO Starter Guide
- Google: How Search organizes information (the index like the index of a book; size)
- sitemaps.org: Sitemaps XML format and the robots.txt Sitemap line
- Bing Webmaster Blog (June 2010): Bing crawler bingbot on the horizon
- Wikipedia: Web crawler (names, seeds and crawl frontier, crawl policies) — facts only
- Wikipedia: Ask.com (Ask Jeeves renamed 2006, closed 1 May 2026) — facts only
- Wikipedia: Excite (web portal) — the US portal closed in August 2026; excite.com now parked (checked 25 Oct 2026) — facts only
This lecture is a first edition. The Kurdish text and terminology are waiting for review by Kurdish IT teachers.ئەم وانەیە چاپی یەکەمە. دەقە کوردییەکە و زاراوەکانی چاوەڕێی پێداچوونەوەی مامۆستایانی کوردی بواری IT ن.